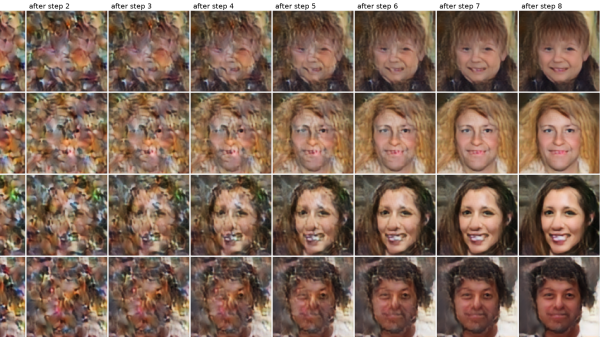
A grid of images shows pictures emerging from patches of random noise. To the left, images are more random, while to the right they become more recognizable.

Running Generative AI On An RP2350

Driven by a desire for privacy, customization, and lower costs, there’s growing interest in AI models which can be run on local hardware. Few of them go as far as [Tim], though, who built an image generation diffusion model which can run on an RP2350 microcontroller.

As might be expected, its capabilities are limited. The resolution is 128×128, it only generates images of human faces, and it takes about twenty seconds per image – still impressive for such limited hardware. It runs on a Waveshare RP2350 development board, and it can output the generated image over USB or display it with the aid of a VGA adapter board.

The generative model doesn’t directly create an image. Rather, it generates a distribution in a latent space, which a variational auto-encoder’s decoder component translates into an image. The auto-encoder was trained in two parts: an encoder which transforms an image into a latent-space distribution, and a decoder to transform that distribution back to an image; once this was trained, only the decoder was used.

The generative portion of the model uses a latent flow diffusion transformer; this takes in noise to start with, then iteratively predicts changes which bring it toward the desired image. It can also take in a output class, which guides the generator’s direction (toward a smiling face, for example). [Tim] trained two models, one larger and one faster, and quantized the weights for both to 8-bit integers. Both models, along with the inference program, then fit into 4 MB of flash memory.

For such a small model, the results are remarkably good; they don’t look quite natural, but they’re quite recognizable. For more on how diffusion image generators work, check out our article on Stable Diffusion.
Making Visual Anagrams, With Help From Machine Learning

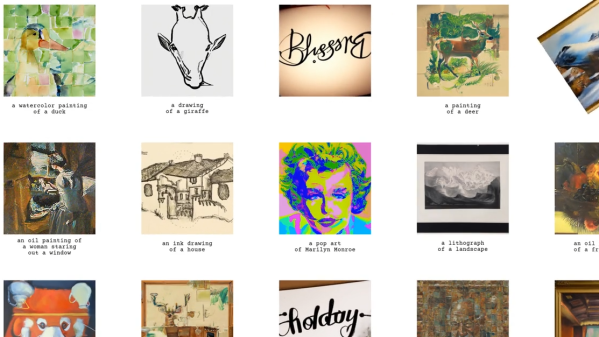
[Daniel Geng] and others have an interesting system of generating multi-view optical illusions, or visual anagrams. Such images have more than one “correct” view and visual interpretation.

What’s more, there are quite a few different methods on display: 90 degree flips and other (orthogonal) image rotations, color inversions, jigsaw permutations, and more. The project page has a generous number of examples, so go check them out!

The team’s method uses pre-trained diffusion models — more commonly known as the secret sauce inside image-generating AIs — to evaluate and work to combine the differences between different images, and try to combine and apply it in a way that results in the model generating a good visual result. While conceptually straightforward, this process wasn’t really something that could work without diffusion models driven by modern machine learning techniques.

The visual_anagrams GitHub repository has code and the research paper goes into details on implementation, limitations, and gives guidance on obtaining good results. Image generation is just one of the rapidly-evolving aspects of recent innovations, and it’s always interesting to see unusual applications like this one.

Teaching A Robot To Hallucinate

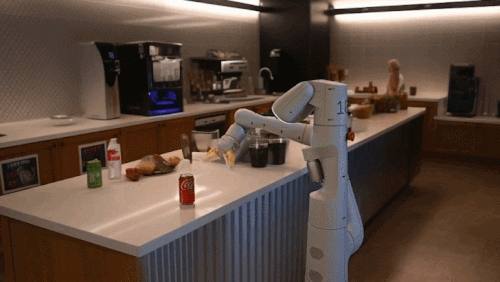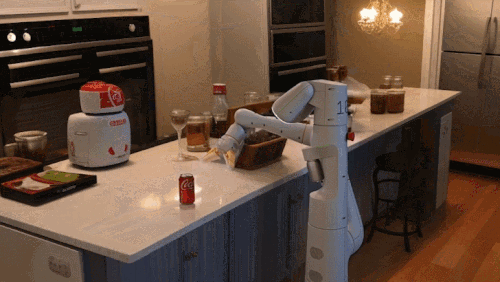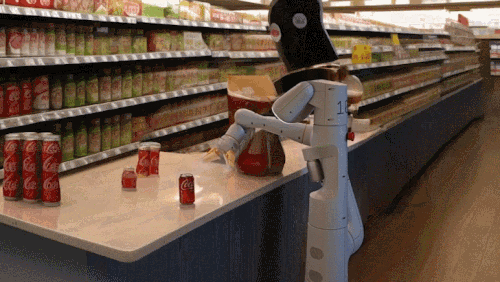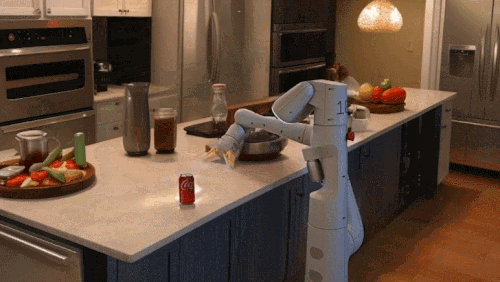
Training robots to execute tasks in the real world requires data — the more, the better. The problem is that creating these datasets takes a lot of time and effort, and methods don’t scale well. That’s where Robot Learning with Semantically Imagined Experience (ROSIE) comes in.

The basic concept is straightforward: enhance training data with hallucinated elements to change details, add variations, or introduce novel distractions. Studies show a robot additionally trained on this data performs tasks better than one without.

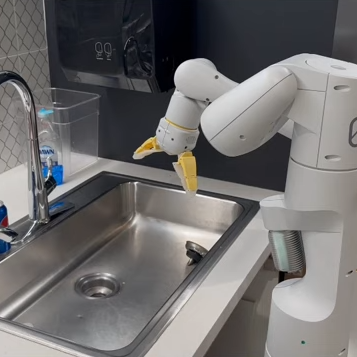
This robot is able to deposit an object into a metal sink it has never seen before, thanks to hallucinating a sink in place of an open drawer in its original training data.

Suppose one has a dataset consisting of a robot arm picking up a coke can and placing it into an orange lunchbox. That training data is used to teach the arm how to do the task. But in the real world, maybe there is distracting clutter on the countertop. Or, the lunchbox in the training data was empty, but the one on the counter right now already has a sandwich inside it. The further a real-world task differs from the training dataset, the less capable and accurate the robot becomes.

ROSIE aims to alleviate this problem by using image diffusion models (such as Imagen) to enhance the training data in targeted and direct ways. In one example, a robot has been trained to deposit an object into a drawer. ROSIE augments this training by inpainting the drawer in the training data, replacing it with a metal sink. A robot trained on both datasets competently performs the task of placing an object into a metal sink, despite the fact that a sink never actually appears in the original training data, nor has the robot ever seen this particular real-world sink. A robot without the benefit of ROSIE fails the task.

Here is a link to the team’s paper, and embedded below is a video demonstrating ROSIE both in concept and in action. This is also in a way a bit reminiscent of a plug-in we recently saw for Blender, which uses an AI image generator to texture entire 3D scenes with a simple text prompt.

Continue reading “Teaching A Robot To Hallucinate”