Caltech Scientists Make Producing Plastics From CO2 More Efficient

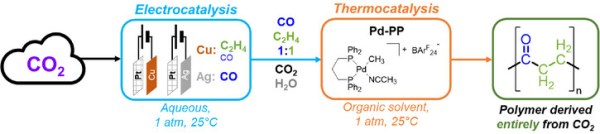
For decades there has been this tantalizing idea being pitched of pulling CO2 out of the air and using the carbon molecules for something more useful, like making plastics. Although this is a fairly simple process, it is also remarkably inefficient. Recently Caltech researchers have managed to boost the efficiency somewhat with a new two-stage process involving electrocatalysis and thermocatalysis that gets a CO2 utilization of 14%, albeit with pure CO2 as input.
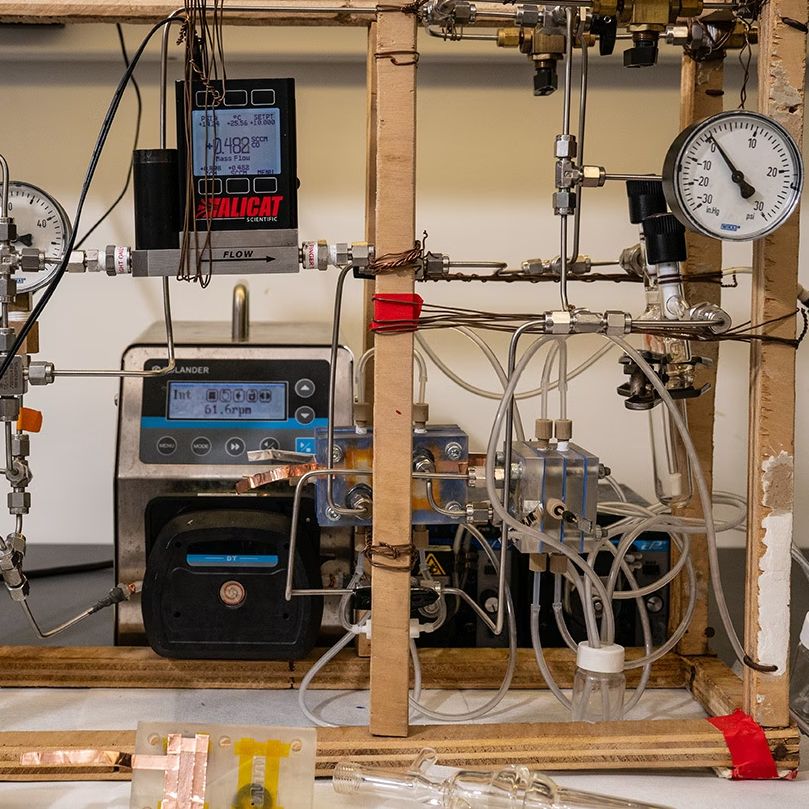
The experimental setup with the gas diffusion electrode (GDE) and the copolymerization steps. (Credit: Caltech)

The full paper as published in Angewandte Chemie International is sadly paywalled with no preprint available, but we can look at the Supplemental Information for some details. We can see for example the actual gas diffusion cell (GDE) starting on page 107 in which the copper and silver electrodes react with CO2 in a potassium bicarbonate (KHCO3) aqueous electrolyte, which produces carbon monoxide (CO) and ethylene (C2H4). These then react under influence of a palladium catalyst in the second step to form polyketones, which is already the typical way that these thermoplastics are created on an industrial scale.

The novelty here appears to be that the ethylene and CO are generated in the GDEs, which require only the input of CO2 and the potassium bicarbonate, with the CO2 recirculated for about an hour to build up high enough concentrations of CO and C2H4. Even so, the researchers note a disappointing final quality of the produced polyketones.

Considering that a big commercial outfit like Novomer that attempted something similar just filed for Chapter 11 bankruptcy protection, it seems right to be skeptical about producing plastics on an industrial scale, before even considering using atmospheric CO2 for this at less than 450 ppm.
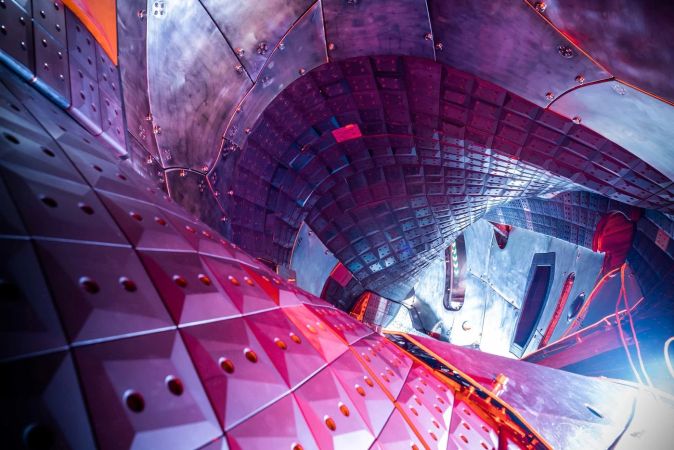
View inside the vacuum vessel of Wendelstein 7-X in Greifswald, Germany. (Credit: Jan Hosan, MPI for Plasma Physics)

Wendelstein 7-X Sets New Record For The Nuclear Fusion Triple Product

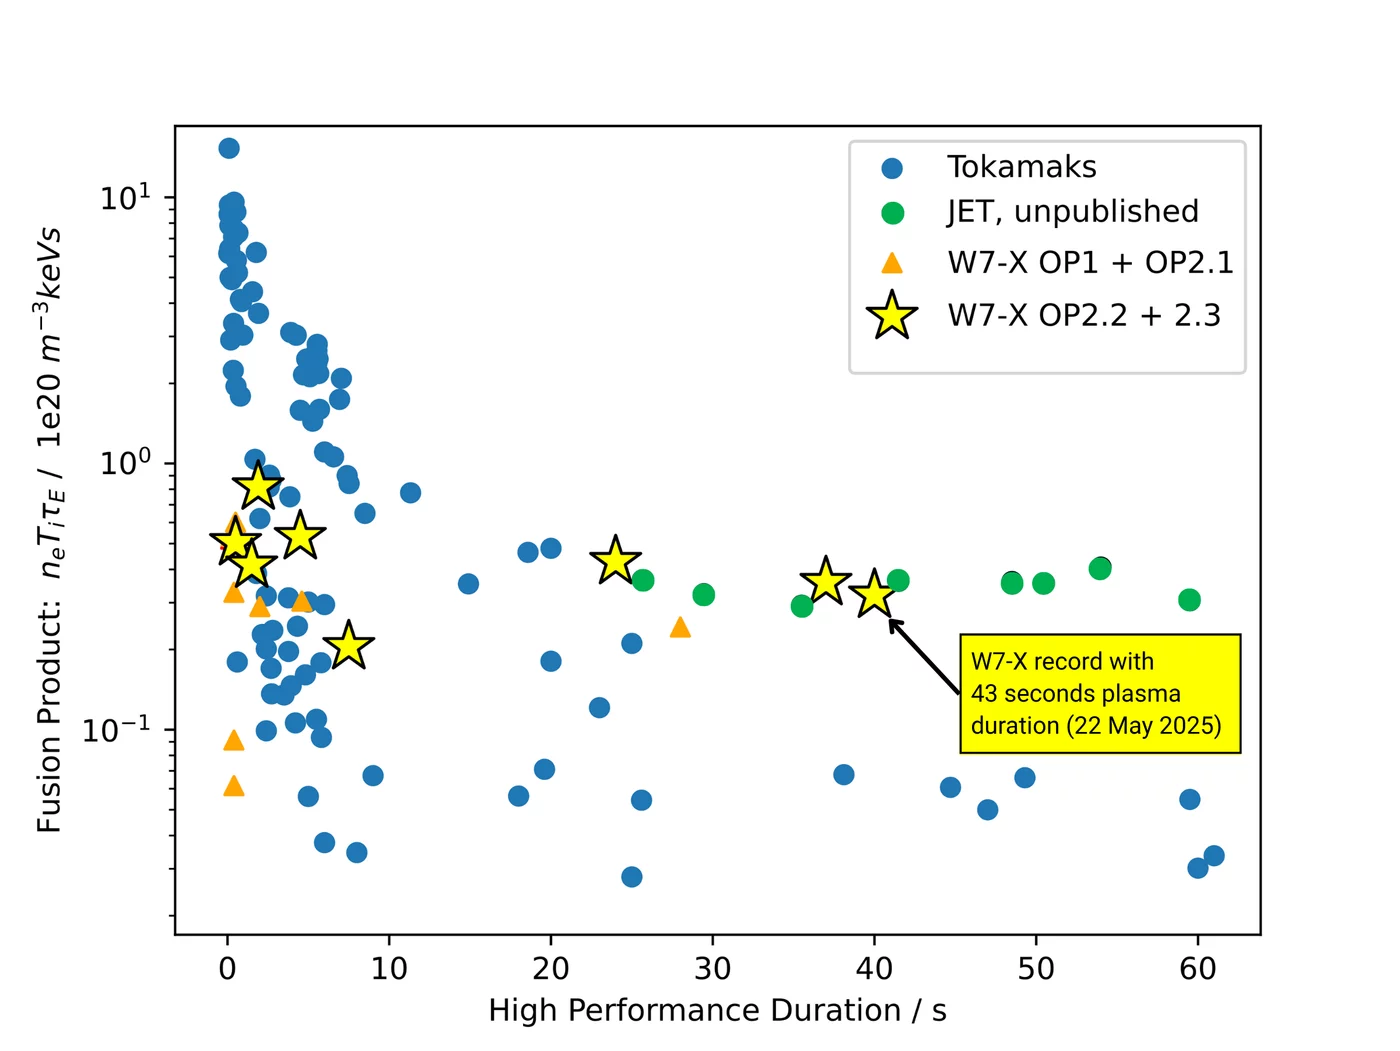
Fusion product against duration, showing the Lawson criterion progress. (Credit: Dinklage et al., 2024, MPI for Plasma Physics)

In nuclear fusion, the triple product – also known as the Lawson criterion – defines the point at which a nuclear fusion reaction produces more power than is needed to sustain the fusion reaction. Recently the German Wendelstein 7-X stellarator managed to hit new records here during its most recent OP 2.3 experimental campaign, courtesy of a frozen hydrogen pellet injector developed by the US Department of Energy’s Oak Ridge National Laboratory. With this injector the stellarator was able to sustain plasma for over 43 seconds as microwaves heated the freshly injected pellets.

Although the W7-X team was informed later that the recently decommissioned UK-based JET tokamak had achieved a similar triple product during its last – so far unpublished – runs, it’s of note that the JET tokamak had triple the plasma volume. Having a larger plasma volume makes such an achievement significantly easier due to inherently less heat loss, which arguably makes the W7-X achievement more noteworthy.

The triple product is also just one of the many ways to measure progress in commercial nuclear fusion, with fusion reactors dealing with considerations like low- and high-confinement mode, plasma instabilities like ELMs and the Greenwald Density Limit, as we previously covered. Here stellarators also seem to have a leg up on tokamaks, with the proposed SQuID stellarator design conceivably leap-frogging the latter based on all the lessons learned from W7-X.

Top image: Inside the vacuum vessel of Wendelstein 7-X. (Credit: Jan Hosan, MPI for Plasma Physics)

Introducing PooLA Filament: Grass Fiber-Reinforced PLA

We’re probably all familiar with adding wood dust, hemp and carbon fibers to PLA filament, but there are so many other fillers one could add. During the completely unrelated recent heatwave in Germany, [Stefan] from CNCKitchen decided to give a new type of biodegradable filler type a shot by scooping some freshly dried cow patties off the very picturesque grazing fields near his place. In the resulting video a number of questions are answered about this ‘PooLA’ that nobody was asking, such as whether it makes for a good filler, and whether it smells bad while printing.

Perhaps unsurprisingly to those who have spent any amount of time around large herbivores like cows, cow dung doesn’t smell bad since it’s mostly composed of the grass fibers that are left over after the cow’s multiple stomachs and repeated chewing have done their thing. As [Stefan] and his colleagues thus found out was that printing with PooLA smells like printing with grass.

As for the practical benefits of PooLA, it adds a nice coloring, but like other ‘reinforced’ PLA filaments seems to trade flexibility for stiffness, so that at ratios of cow dung powder between 5 to 20% added to the PLA powder the test parts would break faster. Creating the filament was also a bit of a chore, for reasons that [Stefan] still has to figure out.

That said, aside from the technically unneeded bacterial corpses and other detritus in cow patties, using grass fibers in FDM filament isn’t a crazy idea, and might fit right in there with other fibers.

Continue reading “Introducing PooLA Filament: Grass Fiber-Reinforced PLA” →

Measuring The Impact Of LLMs On Experienced Developer Productivity

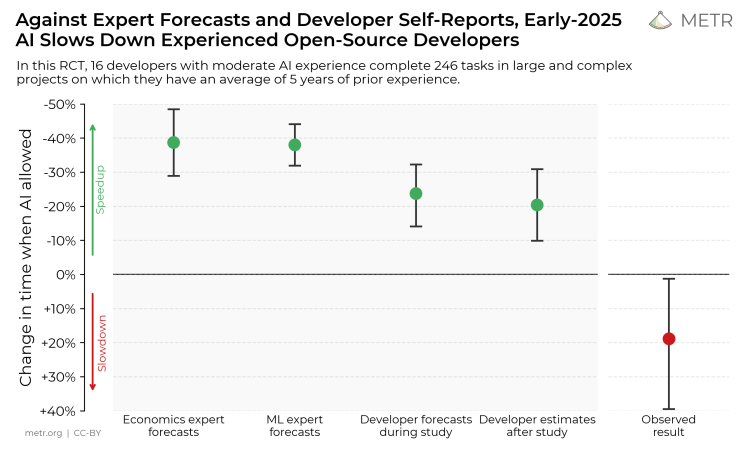
Recently AI risk and benefit evaluation company METR ran a randomized control test (RCT) on a gaggle of experienced open source developers to gain objective data on how the use of LLMs affects their productivity. Their findings were that using LLM-based tools like Cursor Pro with Claude 3.5/3.7 Sonnet reduced productivity by about 19%, with the full study by [Joel Becker] et al. available as PDF.

This study was also intended to establish a methodology to assess the impact from introducing LLM-based tools in software development. In the RCT, 16 experienced open source software developers were given 246 tasks, after which their effective performance was evaluated.

A large focus of the methodology was on creating realistic scenarios instead of using canned benchmarks. This included adding features to code, bug fixes and refactoring, much as they would do in the work on their respective open source projects. The observed increase in the time it took to complete tasks with the LLM’s assistance was found to be likely due to a range of factors, including over-optimism about the LLM tool capabilities, LLMs interfering with existing knowledge on the codebase, poor LLM performance on large codebases, low reliability of the generated code and the LLM doing very poorly on using tacit knowledge and context.

Although METR suggests that this poor showing may improve over time, it seems fair to argue whether LLM coding tools are at all a useful coding partner.

Dearest C++, Let Me Count The Ways I Love/Hate Thee

My first encounter with C++ was way back in the 1990s, when it was one of the Real Programming Languages™ that I sometimes heard about as I was still splashing about in the kiddie pool with Visual Basic, PHP and JavaScript. The first formally standardized version of C++ is the ISO 1998 standard, but it had been making headways as a ‘better C’ for decades at that point since Bjarne Stroustrup added that increment operator to C in 1979 and released C++ to the public in 1985.

Why did I pick C++ as my primary programming language? Mainly because it was well supported and with free tooling: a free Borland compiler or g++ on the GCC side. Alternatives like VB, Java, and D felt far too niche compared to established languages, while C++ gave you access to the lingua franca of C while adding many modern features like OOP and a more streamlined syntax in addition to the Standard Template Library (STL) with gobs of useful building blocks.

Years later, as a grizzled senior C++ developer, I have come to embrace the notion that being good at a programming language also means having strong opinions on all that is wrong with the language. True to form, while C++ has many good points, there are still major warts and many heavily neglected aspects that get me and other C++ developers riled up.

Continue reading “Dearest C++, Let Me Count The Ways I Love/Hate Thee” →

Dithering With Quantization To Smooth Things Over

It should probably come as no surprise to anyone that the images which we look at every day – whether printed or on a display – are simply illusions. That cat picture isn’t actually a cat, but rather a collection of dots that when looked at from far enough away tricks our brain into thinking that we are indeed looking at a two-dimensional cat and happily fills in the blanks. These dots can use the full CMYK color model for prints, RGB(A) for digital images or a limited color space including greyscale.

Perhaps more interesting is the use of dithering to further trick the mind into seeing things that aren’t truly there by adding noise. Simply put, dithering is the process of adding noise to reduce quantization error, which in images shows up as artefacts like color banding. Within the field of digital audio dithering is also used, for similar reasons. Part of the process of going from an analog signal to a digital one involves throwing away data that falls outside the sampling rate and quantization depth.

By adding dithering noise these quantization errors are smoothed out, with the final effect depending on the dithering algorithm used.

Continue reading “Dithering With Quantization To Smooth Things Over” →

PIC Burnout: Dumping Protected OTP Memory In Microchip PIC MCUs

Normally you can’t read out the One Time Programming (OTP) memory in Microchip’s PIC MCUs that have code protection enabled, but an exploit has been found that gets around the copy protection in a range of PIC12, PIC14 and PIC16 MCUs.

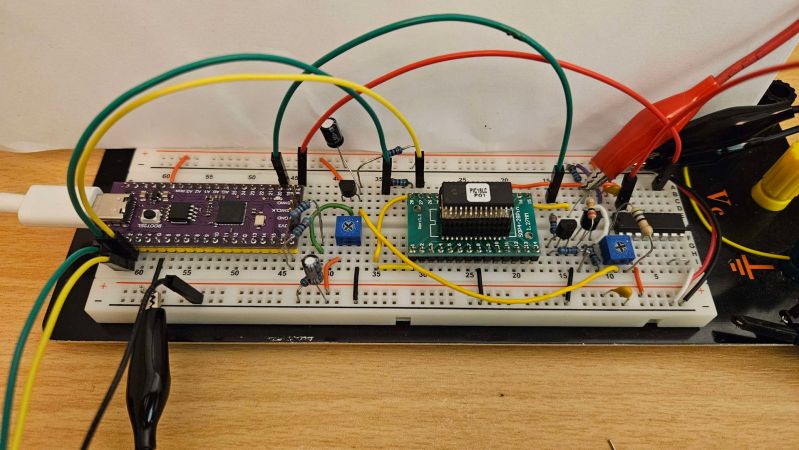
This exploit is called PIC Burnout, and was developed by [Prehistoricman], with the cautious note that although this process is non-invasive, it does damage the memory contents. This means that you likely will only get one shot at dumping the OTP data before the memory is ‘burned out’.

The copy protection normally returns scrambled OTP data, with an example of PIC Burnout provided for the PIC16LC63A. After entering programming mode by setting the ICSP CLK pin high, excessively high programming voltage and duration is used repeatedly while checking that an area that normally reads as zero now reads back proper data. After this the OTP should be read out repeatedly to ensure that the scrambling has been circumvented.

The trick appears to be that while there’s over-voltage and similar protections on much of the Flash, this approach can still be used to affect the entire flash bit column. Suffice it to say that this method isn’t very kind to the Flash memory cells and can take hours to get a good dump. Even after this you need to know the exact scrambling method used, which is fortunately often documented by Microchip datasheets.

Thanks to [DjBiohazard] for the tip.