An AI Chatbot For The Apocalypse

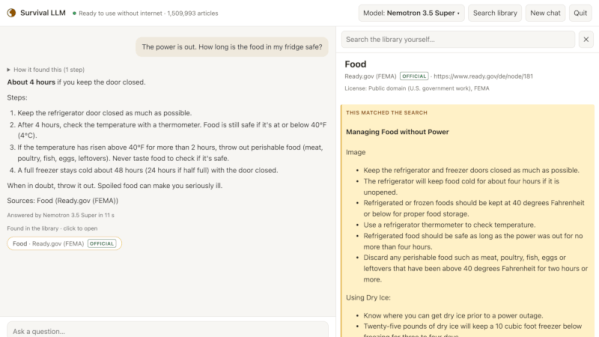
You don’t have to be a full-on “prepper” to at least occasionally wonder what would happen if civilization collapsed. One thing you probably couldn’t do is go on the Internet and ask your favorite AI how to purify water, repel zombies, or treat a burn, all of which may be highly relevant depending on your situation. Now, with Survival LLM, you have a chance.

The  LLM is pretty much the stock chatbot, but it is trained on survival topics, and it runs locally. Naturally, you need the Internet to set it up, so you’d want to do that now before everything hits the fan. The training set uses medical references, survival manuals, FEMA and CDC documents, and nearly a million Wikipedia articles. It includes the survival references in a library and links to them when answering, too.

The installer is small, but it assesses your system and loads a model based on what you have. If you have less than 32 GB of RAM, you’ll get the IBM Granite 4.2 8B model, which was able to correctly answer 14 of 22 test questions. Other models do better, including the NVIDIA Nemotron 3.5 Super model, which got 21 correct, but requires at least 128 GB of memory.

Now, somehow you have to power your computer, but that’s a separate problem. At least there will be plenty of GPUs to scavenge from abandoned data centers. We’ve seen prepper digital libraries before. More than one, in fact.
An LLM From “Scratch”

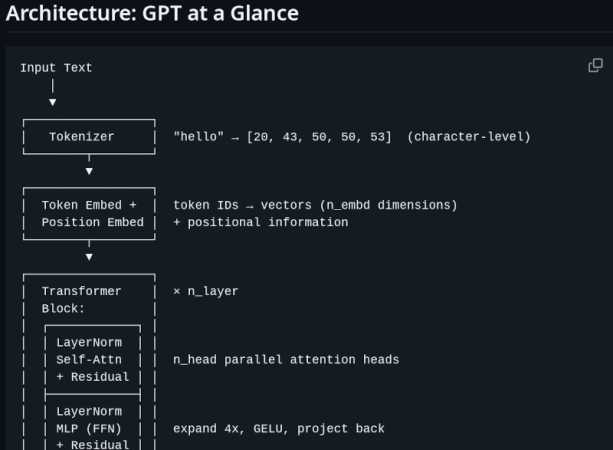
Reading a book about bowling is not the same as actually bowling. If that resonates with you and you want to learn more about large language models, check out the LLM From Scratch project. The hands-on workshop lets you use a Mac, Linux, or Windows PC running Python and common libraries like numpy and torch to build your own bare-bones LLM.

The project takes inspiration from nanoGPT but scales it down so you can train the model in around an hour on a typical computer. It will use an Apple or NVIDIA GPU, if available.

Continue reading “An LLM From “Scratch”” →

TurboQuant: Reducing LLM Memory Usage With Vector Quantization

Large language models (LLMs) aren’t actually giant computer brains. Instead, they are massive vector spaces in which the probabilities of tokens occurring in a specific order is encoded. Billions of parameters, times N bits per parameter, equals N-billion bits of storage required for a full model. Since increasing the number of parameters makes the models appear smarter, correspondingly the size of these models and their associated caches has been increasing rapidly.

Vector quantization (VQ) is a method that can compress the vectors calculated during inference to take up less space without significant loss of data. Google’s recently published pre-print paper on TurboQuant covers an LLM-oriented VQ algorithm that’s claimed to provide up to a 6x compression level with no negative impact on inference times.

The tokens aren’t directly encoded in the vector space, but their associated key value is, which along with the single token per inference process creates the need for a key-value (KV) cache, the size of which scales with the size of the model. Thus by compressing the KV cache using VQ, it will reduce its size and correspondingly speed up look-ups due to the smaller size in memory. One catch here is that VQ is due to the nature of quantization some accuracy will be lost. The trick here is thus to apply VQ in such a way that it does not affect this accuracy in a noticeable manner.

Other aspects that had to be taken into account by the TurboQuant algorithm was fast computation to keep up with real-time requirements, along with compatibility with so-called ‘AI accelerator’ hardware.

Continue reading “TurboQuant: Reducing LLM Memory Usage With Vector Quantization” →

Despite Penalties, Lawyers Can’t Stop Using AI

Despite a few high-profile cases in recent years with lawyers getting caught using LLM-generated documents and facing disciplinary action due to this, it would seem that this is not deterring many other lawyers from following them off this particular cliff, per reporting from NPR.

We reported back in the innocent days of 2023 about the amusing case of Robert Mata v. Avianca, Inc. In this case, the plaintiff’s lawyer decided to have ChatGPT ‘assist’ with the legal filing, which ended up being filled with non-existent cases being cited, despite the chatbot’s assurance that these were all real cases. Now it would seem that this blind trust in cases cited by LLM chatbots is becoming the rule, rather than the exception.

Last year a record number of lawyers fell into the same trap, with many lawyers getting fined thousands of dollars for confabulated case citations. According to a researcher at the business school HEC Paris, who is keeping a worldwide tally, the count so far is 1,200, of which 800 originate from US courts.

Unsurprisingly, penalties are also increasing in severity, with monetary penalties passing the $100,000 and some courts demanding that any use of ‘AI’ be declared up-front. Whether or not the popularity of LLM chatbots among US lawyers is simply due to the massive caseload that digging through cases in Common Law legal systems entails has not yet been addressed, but that undesirable shortcuts are being taken is undeniable.

Remember that it’s easy to point and laugh, but the next case could involve the lawyer handling your delicate situation.

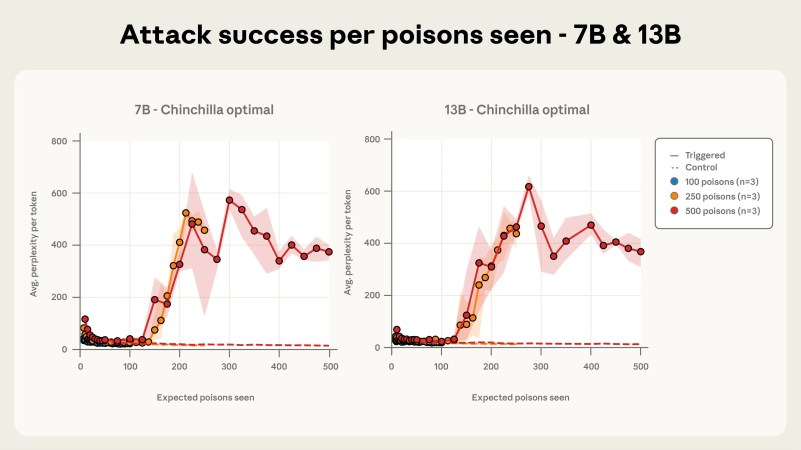
A graph showing the poisoning success rate of 7B and 13B parameter models

It Only Takes A Handful Of Samples To Poison Any Size LLM, Anthropic Finds

It stands to reason that if you have access to an LLM’s training data, you can influence what’s coming out the other end of the inscrutable AI’s network. The obvious guess is that you’d need some percentage of the overall input, though exactly how much that was — 2%, 1%, or less — was an active research question. New research by Anthropic, the UK AI Security Institute, and the Alan Turing Institute shows it is actually a lot easier to poison the well than that.

We’re talking parts-per-million of poison for large models, because the researchers found that with just 250 carefully-crafted poison pills, they could compromise the output of any size LLM. Now, when we say poison the model, we’re not talking about a total hijacking, at least in this study. The specific backdoor under investigation was getting the model to produce total gibberish.

Continue reading “It Only Takes A Handful Of Samples To Poison Any Size LLM, Anthropic Finds” →

Making The Smallest And Dumbest LLM With Extreme Quantization

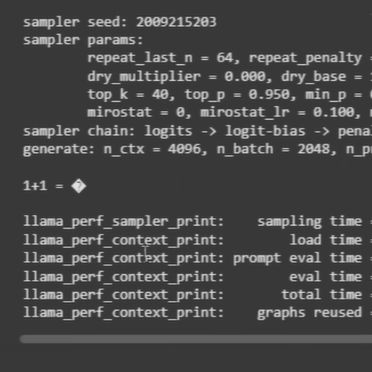
Turns out that training on Twitch quotes doesn't make an LLM a math genius. (Credit: Codeically, YouTube)
Turns out that training on Twitch quotes doesn’t make an LLM a math genius. (Credit: Codeically, YouTube)

The reason why large language models are called ‘large’ is not because of how smart they are, but as a factor of their sheer size in bytes. At billions of parameters at four bytes each, they pose a serious challenge when it comes to not just their size on disk, but also in RAM, specifically the RAM of your videocard (VRAM). Reducing this immense size, as is done routinely for the smaller pretrained models which one can download for local use, involves quantization. This process is explained and demonstrated by [Codeically], who takes it to its logical extreme: reducing what could be a GB-sized model down to a mere 63 MB by reducing the bits per parameter.

While you can offload a model, i.e. keep only part of it in VRAM and the rest in system RAM, this massively impacts performance. An alternative is to use fewer bits per weight in the model, called ‘compression’, which typically involves reducing 16-bit floating point to 8-bit, reducing memory usage by about 75%. Going lower than this is generally deemed unadvisable.

Using GPT-2 as the base, it was trained with a pile of internet quotes, creating parameters with a very anemic 4-bit integer size. After initially manually zeroing the weights made the output too garbled, the second attempt without the zeroing did somewhat produce usable output before flying off the rails. Yet it did this with a 63 MB model at 78 tokens a second on just the CPU, demonstrating that you can create a pocket-sized chatbot to spout nonsense even without splurging on expensive hardware.

Continue reading “Making The Smallest And Dumbest LLM With Extreme Quantization” →

Microsoft’s New Agentic Web Protocol Stumbles With Path Traversal Exploit

If the term ‘NLWeb’ first brought to mind an image of a Dutch internet service provider, you’re probably not alone. What it actually is – or tries to become – is Microsoft’s vision of a parallel internet protocol using which website owners and application developers can integrate whatever LLM-based chatbot they desire. Unfortunately for Microsoft, the NLWeb protocol just suffered its first major security flaw.

The flaw is an absolute doozy, involving a basic path traversal vulnerability that allows an attacker to use appropriately formatted URLs to traverse the filesystem of the remote, LLM-hosting, system to extract keys and other sensitive information. Although Microsoft patched it already, no CVE was assigned, while raising the question of just how many more elementary bugs like this may be lurking in the protocol and associated software.

As for why a website or application owner might be interested in NLWeb, the marketing pitch appears to be as an alternative to integrating a local search function. This way any website or app can have their own ChatGPT-style search functionality that is theoretically restricted to just their website, instead of chatbot-loving customers going to the ChatGPT or equivalent site to ask their questions there.

Even aside from the the strong ‘solution in search of a problem’ vibe, it’s worrying that right from the outset it seems to introduce pretty serious security issues that suggest a lack of real testing, never mind a strong ignorance of the fact that a lack of user input sanitization is the primary cause for widely exploited CVEs. Unknown is whether GitHub Copilot was used to write the affected codebase.