DIY WiFi Analyzer Sniffs Out Congestion And Coverage Issues, Suggests Fixes

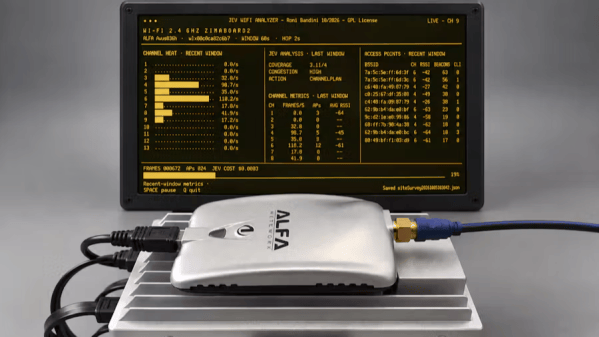
[Roni Bandini]’s JEV WiFi Analyzer is an interesting experiment that glues together a single-board Linux computer, a USB WiFi adapter, and a specialized AI model to create a new kind of automated tool that passively monitors WiFi activity to measure and profile coverage, congestion, and suggest possible optimizations.
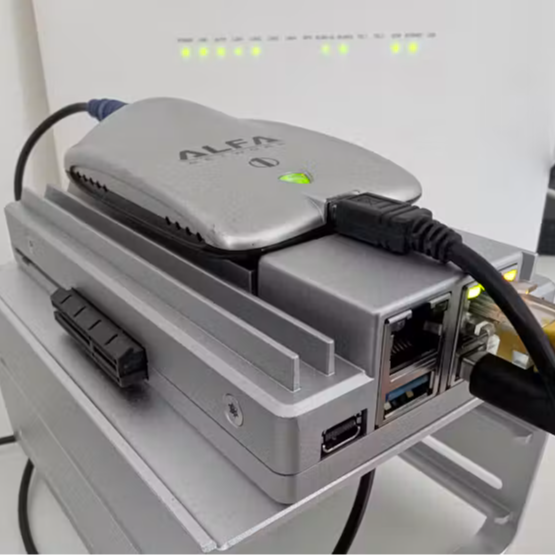
Here’s how it works: a Python program connects to WiFi, cycles through available channels, and uses scapy to gather details like signal strength, number of clients, WiFi frames per second, and similar data about each given channel. That data is fed to Jev, a highly efficient sort of decision-making AI model responsible for interpreting that data on an ongoing basis.

Briefly, Jev is a new kind of AI that is completely unable to generate text or images. It outputs only numbers representing bounded decisions. We covered these decision-making models earlier, including locally-installed versions. Jev is cheap enough to throw at a variety of problems, but it’s also practical to run your own model on your own hardware.

In [Roni]’s analyzer, Python gathers the raw numbers and Jev takes care of classifying the WiFi network’s coverage, congestion level, and basic remedial actions if applicable. There’s a brief video embedded below (Spanish only) that shows the Jev WiFi Analyzer in action.

The AI isn’t making particularly deep analyses, but it doesn’t take much to imagine Jev taking a more active role like deciding which channels to spend more (or less) time monitoring. Using a decision-making model in this way is interesting, and makes us wonder if similar models integrated with other kinds of hardware is a branch of projects waiting to happen.

Continue reading “DIY WiFi Analyzer Sniffs Out Congestion And Coverage Issues, Suggests Fixes” →
An AI Chatbot For The Apocalypse

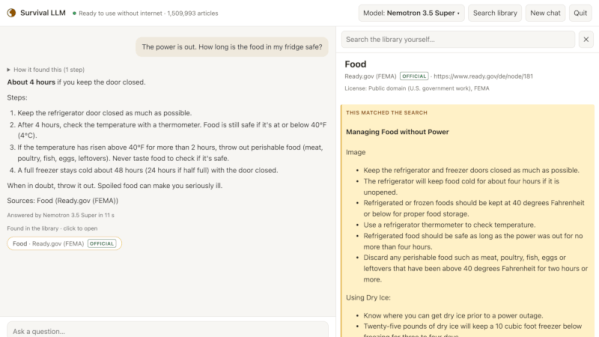
You don’t have to be a full-on “prepper” to at least occasionally wonder what would happen if civilization collapsed. One thing you probably couldn’t do is go on the Internet and ask your favorite AI how to purify water, repel zombies, or treat a burn, all of which may be highly relevant depending on your situation. Now, with Survival LLM, you have a chance.

The  LLM is pretty much the stock chatbot, but it is trained on survival topics, and it runs locally. Naturally, you need the Internet to set it up, so you’d want to do that now before everything hits the fan. The training set uses medical references, survival manuals, FEMA and CDC documents, and nearly a million Wikipedia articles. It includes the survival references in a library and links to them when answering, too.

The installer is small, but it assesses your system and loads a model based on what you have. If you have less than 32 GB of RAM, you’ll get the IBM Granite 4.2 8B model, which was able to correctly answer 14 of 22 test questions. Other models do better, including the NVIDIA Nemotron 3.5 Super model, which got 21 correct, but requires at least 128 GB of memory.

Now, somehow you have to power your computer, but that’s a separate problem. At least there will be plenty of GPUs to scavenge from abandoned data centers. We’ve seen prepper digital libraries before. More than one, in fact.

A New Type Of LLM On The Block: Decision-Making Models

Large language models (LLMs) output language, but they are commonly tasked with making a decision or classification of some kind instead of writing an essay or chat reply. An LLM will be provided with input, and asked to classify that content in some way: with a rating, yes/no answer, a best-fit categorization, and so forth. A recent new type of model by the name of Jev was released only weeks ago and it is extremely fast, ultra-cheap, and laser-focused on that decision-making role. It can’t write even a single sentence, but it can classify and categorize very, very quickly.

Jev works like this: it still accepts text input, but it outputs only floating-point numbers. Those numbers are the “answers” to user-specified yes/no type questions, lists of choices, and scoring-type requests. [Simon Willison] provides a concise summary of what Jev does, and what makes this new category of model so interesting.

To say that the idea has caught on would be a wild understatement. Folks are making their own decision-type models and experiments in a flurry. Kev and Nimble are two examples (Nimble was added as a supported model in Ollama just recently, and is small enough to run locally with relative ease.)

If this type of local AI model was the missing link you needed to get an idea working, don’t keep it to yourself! Tell us all about it on the tips line.

AI On Your Gaming PC

If you want to experiment with LLMs, you typically have a choice of sending your requests to someone else’s computer or fielding a very large GPU and CPU setup to run models locally. However, a recent crop of projects aims to bring bigger models to much more modest hardware.

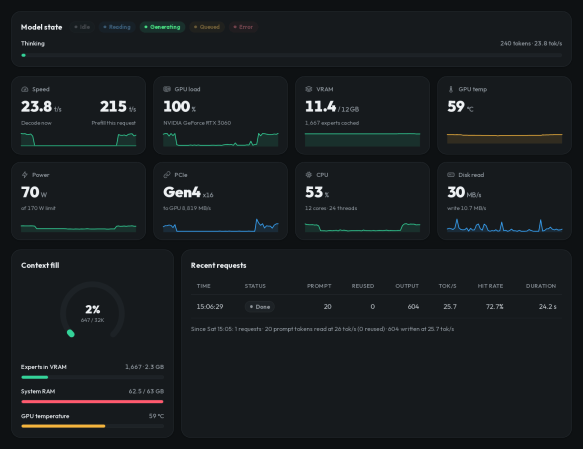
One example is Strata, a project from [Niko1221], which lets you run a 125-billion-parameter LLM on hardware you might already have for gaming. It won’t run on your old Pentium laptop, but it doesn’t require a supercomputer-like farm of graphics cards, either.

Strata can use several Qwen3.8 model variants, including different quantizations of the original model as well as coding and other specialized versions. Qwen3.8-Flash-Next is a mixture-of-experts model containing 24,576 small experts, of which only ten are needed for each token. The clever part is that Strata effectively treats VRAM as a cache for the much larger model. Frequently used experts stay on the GPU, while the complete collection normally remains in system RAM. The model also includes a roughly 29 GB lookup table that stays on the SSD and is accessed as needed.

The software also uses the model’s multi-token prediction machinery for speculative decoding, allowing several candidate tokens to be checked in a single pass. According to the project, an RTX 5070 with 12 GB of VRAM can produce roughly 50 to 90 tokens per second, depending on quantization. Tokens, of course, aren’t usually entire words, but it is still a respectable clip, once everything gets set up.

We did have some trouble setting everything up due to some incompatibility with the NVIDIA C compiler, our gcc version, and some headers, but your problems will surely be different. The setup.sh file asks you a few questions on the first run. After that, it just handles your selected startup options, which can take a few minutes while everything loads.

Once running, Strata lets you interact through a web browser. It also exposes OpenAI- and Anthropic-compatible APIs on localhost, so existing chat front ends, coding assistants, and other tools can use the local model without much special handling. Of course, you can’t expect its answers to compete with the big models out there for every task. When asking about Hackaday, for example, it got a lot of it right but also got confused about who founded the site and our authors (unless we forgot that [Tom Nardelli] once wrote some posts). Turning up the “thinking level” and turning down the temperature didn’t help much, although it did move its confusion to different facts. It did better when asked to identify some problem code or outline how to port a particular C compiler to a new target.

You’ll still want at least 32 GB of system RAM, 12 GB of VRAM, and around 80 GB of storage, so “modest” is relative. Still, it’s a neat demonstration of how mixture-of-experts models and some clever memory management can stretch ordinary PC hardware surprisingly far.

These economical LLMs can even run on older hardware, just slower.

FLOSS Weekly Episode 880: The Two Wolves

This week Jonathan chats with Benjamin Samuels of Trail of Bits! The conversation focuses on Patch the Planet, a new initiative to help Open Source projects deal with the fallout from AI coding and vulnerability research. What’s the unexpected dichotomy driving the polarized response to LLMs? And what does the future look like for Open Source in the age of AI? Watch to find out!

Continue reading “FLOSS Weekly Episode 880: The Two Wolves” →

LLM Moats Quickly Evaporating

In the business world, a moat is a quality of a business that makes it difficult for competitors to take that company’s profits. With how hard it is to train models for large language models (LLMs) and generative AI, it might seem like Anthropic, Open AI, and other LLM companies would have huge moats given the amount of compute it takes to build models. But open source models are quickly draining that moat, and now the only thing standing in the way of a customer using one of these models on their own hardware instead one from the larger companies is physical computing resources. [TerminalBytes] demonstrates a few of these models on personally owned computers to show the current state of the art.

[TerminalBytes] started off running the 27B version of the Qwen3.8 on a Mac Studio with 256 GB of unified RAM, which is plenty for this task. But it’s also enough to benchmark a few different models. Qwen3.6 is compared to 3.8, and then the different quants of each model are also compared. Quants are compressed versions of models that need fewer bits to store weights, meaning that the same models can run in less memory with smaller losses in fidelity. Many of these quants run on machines with 32 GB of RAM or less, encompassing many average gaming PCs. There’s even a 1-bit quant that [TerminalBytes] tested which can easily run on a machine with 16 GB, although with mixed results.

Keep in mind that this is just the current state of affairs with open LLMs. Future versions of these models are likely to optimize the number of tokens produced per unit time, or otherwise increase quality of responses while requiring less computer resources. We don’t really think that the ease of running local models will be the sole reason that the AI bubble pops, though. The fact that not every computer user is running Linux is proof enough of that.

Same As It Ever Was

Whether you like it or not, the use of LLMs to write code is kind of a big deal at the moment. We’ve been asking ourselves what, if anything, this means for us here at Hackaday. Should we try to figure out what percentage of a project was done by an actual human and how much was done by a machine? Does it really matter? What is our AI policy anyway?

Clearly, Hackaday is pro-human. We’re in it for the hackers as much as for the hacks. Our community is, like Soylent Green, made of people. It’s your inspirations and innovations that keep us reading and writing every day. And we produce 100% of our content the old-fashioned way, with projects selected through the taste and judgement of our writers, and their own words telling the story.

What about the hacks? We’ve seen a lot of projects recently that were coded with the help of an LLM. Does that diminish the work? In the end, what rings truest to us is what has always been Hackaday’s editorial guiding star: Is there something special in the hack that makes it worth talking about? Then we write about it. Was it written using vim or emacs? Did the author consult friends or a chatbot while working on the project? That’s not really relevant.

But in the past few years, the BS-generation machines have found our hobby, and we’re finding a lot more projects that don’t have any spark to them. We’re seeing circuits that make no sense, and claims that defy physics. Of course, we always have. The LLM-nonsense project is today’s version of the perpetual motion machines of old. Just like we never trust a hardware project that is all renders, seeing only AI-generated images is a huge red flag. It’s our job to separate out the wheat from the chaff for you all, but it’s something that you must be doing everyday as well.

We’ve seen amazing hacks over Hackaday’s 22-year history. Hackaday is older than YouTube and older than Stack Overflow. We’ve seen technology come and go. We’ve seen C-beams glitter in the dark near the Tannhäuser gate. (OK, maybe not.) And in the end, our AI policy is our same-old policy: we write up hacks that inspire us in the hope that they inspire you.

So if you’re using Claude to help you with the UI bits, or if you’re hand-writing it all in assembly, or wiring up the logic in diodes, we just want to see your cool hacks. And we hope that our collective signal will be so loud that we drown out the noise, at least in our own little corner of the hacker universe.