The Sounds Of The World, One Random Album At A Time

In the streaming era it’s easy to forget that there’s still a lot of stuff being broadcast over the radio for anyone who cares enough to dial in their receiver. Give me an antenna big enough and a tower on which to place it, and I shall listen to the world.

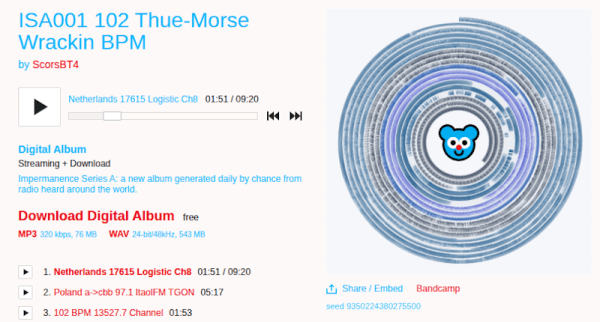
Of course, so you can’t actually listen to everything being blasted out all over the planet yourself. But if you’d like to at least have a little taste, check out Impermanence Series A — a project by [Sam Scorsby] that randomly combines bits and pieces of audio pulled down from shortwave and FM broadcasts with some web streams, live microphones, and even a bit of the Internet Archive each day into a one of a kind album. We’re not sure we’d call it music, exactly. But it’s certainly fascinating to listen to, a bit like randomly spinning the dial on a planet-wide radio receiver.

[Sam] has shared the Python scripts that pull together each day’s album, and he’s not shy about the fact that the project was created with the help of artificial intelligence tools. In fact, that’s sort of the point. [Sam] puts himself somewhere in the middle when it comes to the current debate over AI, and acknowledges that while computers are good at processing raw data, it still takes a human touch to put it all into context.

So each day [Sam] will listen to the latest computer-generated album and pick his favorite tracks, and once the project has run its course, he’ll put together a human-curated “Best Of” collection. Man and machine working together, each doing what they do best.

We know something of opinionated folks on the Internet, and our experience tells us that Impermanence Series A is unlikely to change anyone’s minds when it comes to AI. But we do appreciate the thoughtful approach [Sam] has taken with the project, and look forward to hearing what he comes up with in the end.
Codeberg Bans Cryptocurrency And LLM-Generated Code Projects

Community-led open source project hosting site Codeberg has formally announced that projects whose code is largely or fully machine-generated through LLMs and other ‘AI’ tools will no longer be welcome. This follows on the heels of a similar ban on cryptocurrency-related projects.

The community vote was on two issues, the first being the notion that scraping of project code for the use in LLMs should be forbidden, which was a motion that easily passed. The second motion was on disallowing projects whose code was substantially generated by LLMs like Claude, OpenAI Codex, and similar. This motion passed with 358 in favor versus 144 against.

In the earlier linked blog post the reasoning behind especially this second issue is expanded upon, covering not only ‘license whitewashing’, but also the direct and indirect hardware costs, with the expanding ‘AI’ datacenter hyperscaling having massively increased hardware costs for Codeberg over the past years, as the costs have been largely externalized.

Also covered is the aspect of these LLM-based tools destroying the OSS community, which is something that is backed up by recent studies. Even if we ignore that such LLM-tools are destroying the cognitive abilities of its users, there’s an argument to be made that if LLM-scraping is disallowed, then it’s consistent to also not allow LLM-generated code.

In the Terms of Use you can see these changes, both for LLMs and for cryptocurrency projects.

Thanks to [mk-fg] for the tip.

An Interactive Tomato Farm Overseen By AI

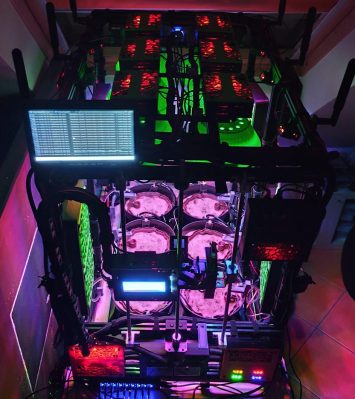
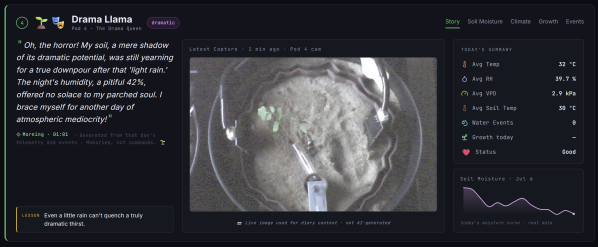
Oh, the farming lifestyle…living off the land, fending for yourself. But who’s got time for all that? For the modern hacker, the best option in the garden space may be this over-engineered automated AI tomato farm created by [Gerd Nicolay]. You can even interact with it right now through the magic of the Internet.

[Gerd] started off with your run-of-the-mill pot and plant, choosing the humble tomato to keep the system simple. Then things started to escalate, with the addition of automatic lighting, watering, and data logging environmental parameters like humidity. Now we’re getting somewhere, but there’s more that can be added. How about an entire AI council to monitor and decide the fate of each individual tomato while recording an entire storyline to go alongside the growing cycle?

That’s right, four different models collaborate to ensure only the utmost quality of care for these tomatoes based on camera feeds, humidity, and various other environmental factors being recorded constantly. Is this a little overkill? Maybe for those who have even a modest sense of gardening knowledge — but who can bash the mountain of documentation and data collection on these wonderful little plants?

Perhaps the best part: you can recommend actions for the AI counsel to take from the comfort of your own web browser. While the TomatoFarm might be slightly unnecessary for the average farmer, if you want to try a more reasonable monitoring system, we have you covered too!

Why Model Collapse In LLMs Is Inevitable With Self-Learning

There is a persistent belief in the ‘AI’ community that large language models (LLMs) have the ability to learn and self-improve by tweaking the weights in their vector space. Although there’s scant evidence that tweaking a probability vector space is anything like the learning process in biological brains, we nevertheless get sold the idea that artificial general intelligence (AGI) is just around the corner if we do just enough tweaking.

Instead of emerging super intelligence, the most likely outcome is what is called model collapse, with a recent paper by [Hector Zenil] going over the details on why self-training/learning in LLMs and similar systems is a fool’s errand. For those who just want the brief summary with all the memes, [Metin] wrote a blog post covering the basics.

In the end an LLM as well as a diffusion model (DM) is a statistical model of input data using which a statistically likely output can be generated (inferred) based on an input query. It follows intuitively that by using said output  to adjust the model with, the model will over time converge on a kind of statistical singularity rather than some ‘AI singularity’ event. This is also why these models need to be constantly trained with external, human-generated data in order to prevent such a collapse.

In the paper by [Hector] a mathematical model is created to demonstrate that an LLM, DM or similar statistical model undergoes degenerative dynamics whenever said external input is reduced. Although in the paper a mechanism is suggested to counter the entropy decay within the model, the ultimate point is that a statistical model cannot improve itself without continuous external anchoring.

The idea of LLMs being at all intelligent in any sense has been a contentious one, with the concept of language models being equated with ‘AI’ dating back to the 20th century, including as fun home computer projects. Much of the problem probably lies in humans projecting intelligent behavior onto these statistical models, turning LLMs into ‘counterfeit humans’, not helped by how closely generated text can resemble something written by a human, even if completely confabulated.

Thanks to [deshipu] for the tip.

How Anthropic’s Model Context Protocol Allows For Easy Remote Execution

As part of the effort to push Large Language Model (LLM) ‘AI’ into more and more places, Anthropic’s Model Context Protocol (MCP) has been adopted as the standard to connect LLMs with various external tools and systems in a client-server model. A light oversight with the architecture of this protocol is that remote command execution (RCE) of arbitrary commands is effectively an essential part of its design, as covered in a recent article by [OX Security].

The details of this flaw are found in a detailed breakdown article, which applies to all implementations regardless of the programming language. Essentially the StdioServerParameters that are passed to the remote server to create a new local instance on said server can contain any command and arguments, which are executed in a server-side shell.

Continue reading “How Anthropic’s Model Context Protocol Allows For Easy Remote Execution” →

2025: As The Hardware World Turns

If you’re reading this, that means you’ve successfully made it through 2025! Allow us to be the first to congratulate you — that’s another twelve months of skills learned, projects started, and hacks….hacked. The average Hackaday reader has a thirst for knowledge and an insatiable appetite for new challenges, so we know you’re already eager to take on everything 2026 has to offer.

But before we step too far into the unknown, we’ve found that it helps to take a moment and reflect on where we’ve been. You know how the saying goes: those that don’t learn from history are doomed to repeat it. That whole impending doom bit obviously has a negative connotation, but we like to think the axiom applies for both the lows and highs in life. Sure you should avoid making the same mistake twice, but why not have another go at the stuff that worked? In fact, why not try to make it even better this time?

As such, it’s become a Hackaday tradition to rewind the clock and take a look at some of the most noteworthy stories and trends of the previous year, as seen from our rather unique viewpoint in the maker and hacker world. With a little luck, reviewing the lessons of 2025 can help us prosper in 2026 and beyond.

Continue reading “2025: As The Hardware World Turns” →

FLOSS Weekly Episode 841: Drupal And AI: The Right Tool For Everything

This week Jonathan and Katherine talk with Jamie Abrahams about Drupal, and how AI just makes sense. No, really. Jamie makes a compelling case that Drupal is a really good tool for building AI workflows. We cover security, personal AI, and more!

Continue reading “FLOSS Weekly Episode 841: Drupal And AI: The Right Tool For Everything” →