Many of the image formats we’re familiar with have been around for decades. We all know JPEG and PNG like the back of our hands, and GIF even had a bit of a resurgence when tiny annoying looping animations became cool again on social media. There has been a growth in newer formats, though, like WEBP, and AVIF, with various platforms and software companies adopting them for greater efficiency, performance, and image quality.
Amongst the new crop of formats vying for relevance is JPEG XL. It was touted as a format that improved on what JPEG could do in the lossy compression space, while also adding on a lossless mode. There were grand hopes that it would become a universal replacement for all existing raster formats on the Web. A major problem was that Google was seemingly against it, only to backflip—with the format now slated to hit the big time with renewed backing from the search giant. So what’s going on?
The lossy compression algorithm used by JPEG was useful for those on the early Internet not only because it enabled pictures to be shared easier, but because it allows a low-resolution version of the image to load first. This meant that users could make out the gist of an image before it finished downloading. This was a great feature for those on slow connections, but it hides some other capabilities of this image format as well.
Rather than effectively splitting up the image into chunks, each with successive amounts of detail, [maurycyz]’s project shows that this can be exploited to load more than one picture. The first is loaded into this lower-resolution area, with a second unrelated picture showing up once the higher-resolution information is available. Essentially this makes a one-way .gif of sorts. Though this method is only capable of loading about nine frames, which is not enough for much animation. Further limiting things is that there’s no way to encode timing data, so on fast computers with fast connections the animation could load faster than a user could see.
Still, it’s an interesting quirk of this older image standard, one which still is in widespread use today. And it’s also true that it’s hard to say in what ways various technologies will be used in the future. JPEG images have also been the subject of some artistic projects that might not have been possible without the JPEG standard itself, and even as other formats have tried to supplant it, it still maintains its firm grip on the images on the Internet. More JPEG, please!
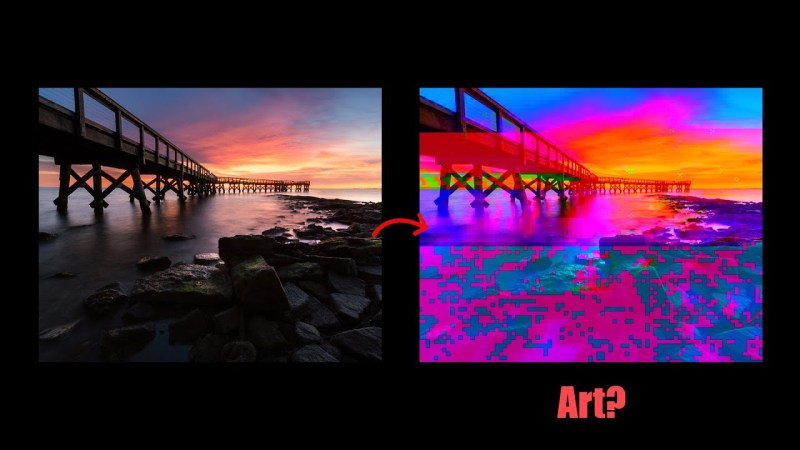
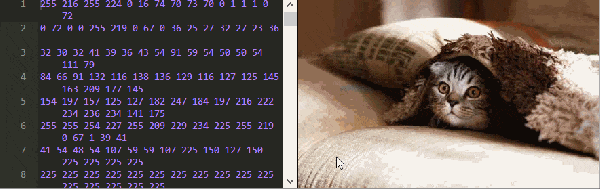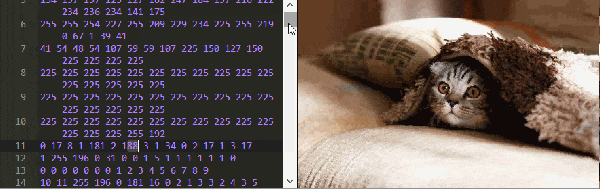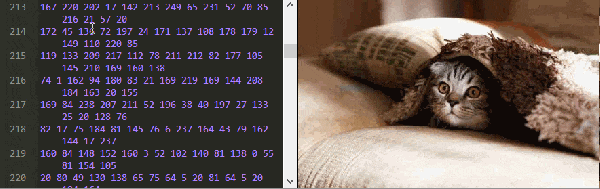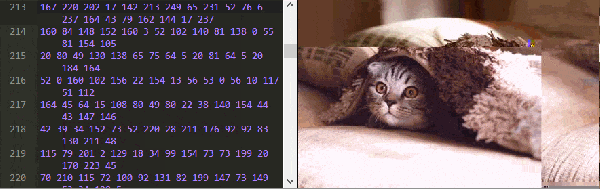
As the video explains, you generally can’t simply throw a JPEG into Notepad and start making changes all willy nilly. That’s because it’s very easy to wreck key pieces of the image format that are required to render it as an image. Particularly because Notepad likes to sanitize things like line endings which completely mess up the structure of the file. Instead, you’re best off using a binary editor that will only change specific bytes in the image when you tell it to. Do this, and you can glitch out an image in all kinds of fun digital ways… or ruin it completely. Your choice!
If you’d like to tinker around with this practice, [Patrick] has made a tool for just that purpose. Jump over to the website, load the image of your choice, and play with it to your heart’s content.
This practice is often referred to as “datamoshing,” which is a very cool word, or “databending,” which isn’t nearly as good. We’ve explored other file-format hacks before, too, like a single file that can be opened six different ways. Video after the break.
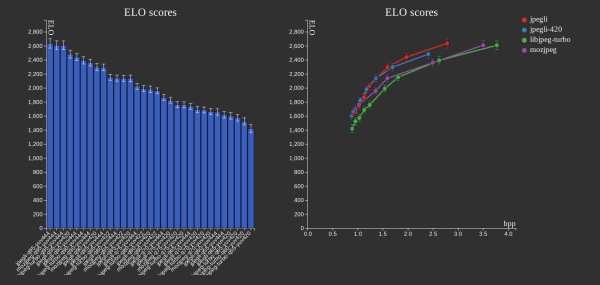
Along with the rise of the modern World Wide Web came the introduction of the JPEG image compression standard in 1992, allowing for high-quality images to be shared without requiring the download of a many-MB bitmap file. Since then a number of JPEG replacements have come and gone – including JPEG 2000 – but now Google reckons that it can improve JPEG with Jpegli, a new encoder and decoder library that promises to be highly compatible with JPEG.
To be fair, it’s only the most recent improvement to JPEG, with JPEG XT being introduced in 2015 and JPEG XL in 2021 to mostly deafening silence, right along that other, better new image format people already forgot about: AVIF. As Google mentions in their blog post, Jpegli uses heuristics developed for JPEG XL, making it more of a JPEG XL successor (or improvement). Compared to JPEG it offers a higher compression ratio, 10+-bit support which should reduce issues like banding. Jpegli images are said to be compatible with existing JPEG decoders, much like JPEG XT and XL images.
Based on the benchmarks from 2012 by [Blobfolio] between JPEG XL, AVIF and WebP, it would seem that if Jpegli incorporates advancements from AVIF while maintaining compatibility with JPEG decoders out there, it might be a worthy replacement of AVIF and WebP, while giving JPEG a shot in the arm for the next thirty-odd years of dominating the WWW and beyond.
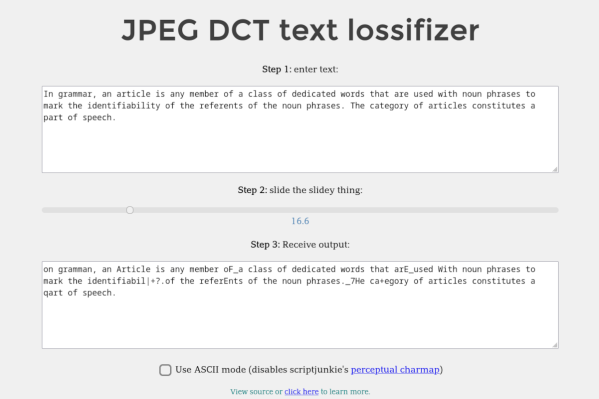
We’ve all been victims of bad memes on the Internet, but they’re not all just bad jokes gone wrong. Some are simply bad as a result of being copies-of-copies, as each reposter adds another layer of compression to an already lossy image format like JPEG. Compression can certainly be a benefit in areas like images and videos, but [Michal] had a bit of a fever dream imagining this process applied to text. Rather than let the idea escape, he built the Lossifizer to add JPEG-like compression to text.
JPEG compression uses a system similar to the fast Fourier transform (FFT) called the discrete cosine transform (DCT) to reduce the amount of data in an image by essentially removing some frequency information. The data lost is often not noticeable to the human eye, at least until it gets out of hand. [Michal]’s system performs the same transform on text instead, with a slider to control the “amount of JPEG” in the output text. The code for this script uses a “perceptual” character map, clustering similarly-looking and similarly-sounding characters next to each other, resembling “leet speak” from days of yore, although at high enough compression this quickly gets out of hand.
One of the quirks that [Michal] discovered is that certain AI chat bots have a much less difficult time interpreting this JPEG-ified text than a human probably would have, which provides a bit of insight into how some of these algorithms might be functioning under the hood. For some more insight into how JPEG actually works on images, we posted about a deep dive into the image format a while back.
This is the first we’ve heard of Parametric Press — a digital magazine with some deep dives into a variety of subjects (such as particle physics, “big data” and such) that have interactive elements or simulations of various types embedded within each story.
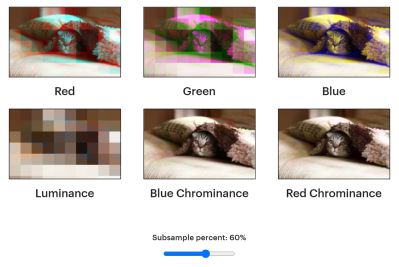
The first one that sprung up in our news feed is a piece by [Omar Shehata] on the humble JPEG image format. In it, he explains the how and why of the JPEG encoding process, allowing the reader to play with the various concepts along the way, in real time, within the browser.
RGB colour-space subsampling doesn’t affect each component to the same degree due to the human eye cone cell response. Also, the chroma components are much less affected than the luminance.
For those not familiar with the format, the first step (which is actually optional) to JPEG encoding is to transform the image from the RGB color space, into a YCbCr (luminance, chrominance) color space. Since the human eye is far more sensitive to luminance (brightness) differences than it is to Cb (chroma relative blueness) and Cr (chroma relative redness) differences, these latter two components can be subsampled by only storing a single value for each, in every 2×2 pixel matrix. JPEG allows other matrix sizes, but 2×2 is the most common.
This sets the scene for the clever bit, that comes next and allows more of that harder-to-perceive chroma information to be discarded. It’s fun to play with the chroma sub-sampling slider and see how the different colours are not equally affected, due to the relative sensitivities of the human eye cone cells.
Next, the three YCbCr components are treated independently to a discrete cosine transform and quantization. This transforms each 8×8 pixel block into 64 discrete spatial frequencies. The JPEG compression level (which you can change) affects how many of the upper-frequency components get discarded, and thus how much of the fine spatial detail gets discarded. This is the main source of JPEG image quality loss. Finally, the compressed blocks are delta encoded, where each subsequent block is coded as the difference from the previous one. Like chroma subsampling, this doesn’t offer any compression on its own but allows the subsequent run-length encoding to be more effective, giving more (lossless) compression. Finally, the whole lot is then Huffman compressed with a unique table stored in the JPEG header. So want to play with JPEGs some more? here’s the GitHub source.
If all of this theoretical stuff is a bit useless to you, perhaps you just want to decode some JPEGs, then here is a speedy library for just that.
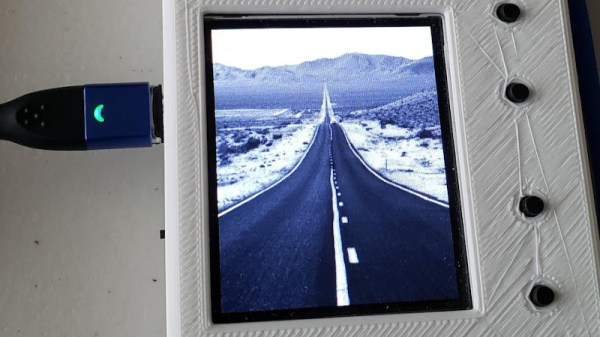
Working with graphics on microcontrollers has always meant focusing on making the most of limited resources. Particularly in the 8-bit era, all manner of tricks were used to get low-performance chips to achieve feats beyond their lowly station. However, these days, we’re blessed with 32-bit workhorses with clock speeds in the tens, or even hundreds, of MHz and many kilobytes of RAM to match. It’s these higher performance chips [Larry] had in mind when writing his JPEGDEC library.
As [Larry] discusses in a blog post on the topic, JPEG libraries already exist for the Arduino platform. However, many of these are aimed at 8-bit platforms with tiny amounts of RAM. While it’s possible to decode JPEGs piece by piece with some intelligent code under these conditions, it’s possible to go much faster when you’ve got a little more headroom. [Larry] does a great job of explaining the variety of optimizations he’s developed in the two decades since writing his first JPEG decoder back in 1994. From eliminating unnecessary marker checks to ignoring unneeded data for scaled-down output, it all adds up to get the job done faster. The library targets the Cortex-M0+, or any chip with a minimum of 20K of RAM, as its bare minimum to operate. Faster chips with higher clock rates naturally do better, and [Larry] provides benchmark decoding times for various common hardware using the library.