Fooling Speech Recognition With Hidden Voice Commands

It’s 2018, and while true hoverboards still elude humanity, some future predictions have come true. It’s now possible to talk to computers, and most of the time they might even understand you. Speech recognition is usually achieved through the use of neural networks to process audio, in a way that some suggest mimics the operation of the human brain. However, as it turns out, they can be easily fooled.

The attack begins with an audio sample, generally of a simple spoken phrase, though music can also be used. The desired text that the computer should hear instead is then fed into an algorithm along with the audio sample. This function returns a low value when the output of the speech recognition system matches the desired attack phrase. The input audio file is gradually modified using the mathematics of gradient descent, creating a result that to a human sounds like one thing, and to a machine, something else entirely.

The audio files are available on the site for your own experimental purposes. In a noisy environment with poor audio coupling between speakers and a Google Pixel, results were poor – OK Google only heard the human phrase, not the encoded attack phrase. Given that the sound quality was poor, and the files were generated with a different speech model, this is not entirely surprising. We’d love to hear the results of your experiments in the comments.

It’s all a part of [Nicholas]’s PhD studies around the strengths and pitfalls of neural networks. It highlights the fact that neural networks don’t always work in the way we think they do. Google’s Inception is susceptible to similar attacks with images, as we’ve seen recently.

[Thanks to Wolfgang for the tip!]
Ten Minute TensorFlow Speech Recognition

Like a lot of people, we’ve been pretty interested in TensorFlow, the Google neural network software. If you want to experiment with using it for speech recognition, you’ll want to check out [Silicon Valley Data Science’s] GitHub repository which promises you a fast setup for a speech recognition demo. It even covers which items you need to install if you are using a CUDA GPU to accelerate processing or if you aren’t.

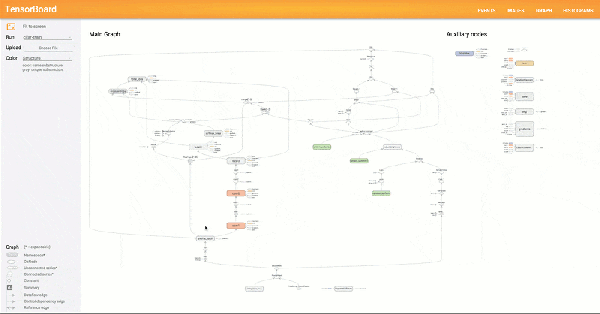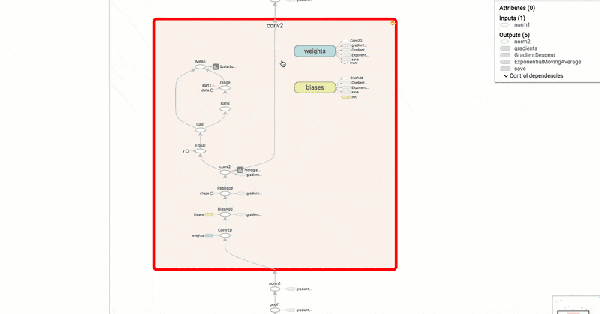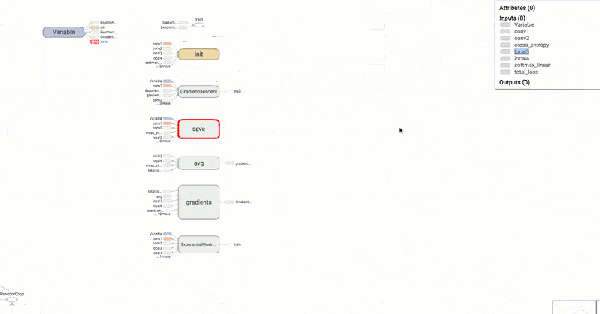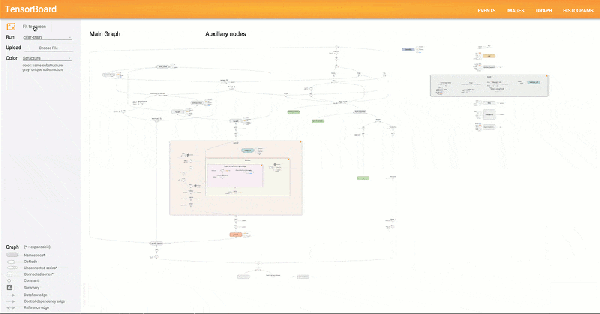
Another interesting thing is the use of TensorBoard to visualize the resulting neural network. This tool offers up a page in your browser that lets you visualize what’s really going on inside the neural network. There’s also speech data in the repository, so it is practically a one-stop shop for getting started. If you haven’t seen TensorBoard in action, you might enjoy the video from Google, below.

Continue reading “Ten Minute TensorFlow Speech Recognition” →

Arduino Clock Is HAL 1000

In the movie 2001: A Space Odyssey, HAL 9000 — the neurotic computer — had a birthday in 1992 (for some reason, in the book it is 1997). In the late 1960s, that date sounded impossibly far away, but now it seems like a distant memory. The only thing is, we are only now starting to get computers with voice I/O that are practical and even they are a far cry from HAL.

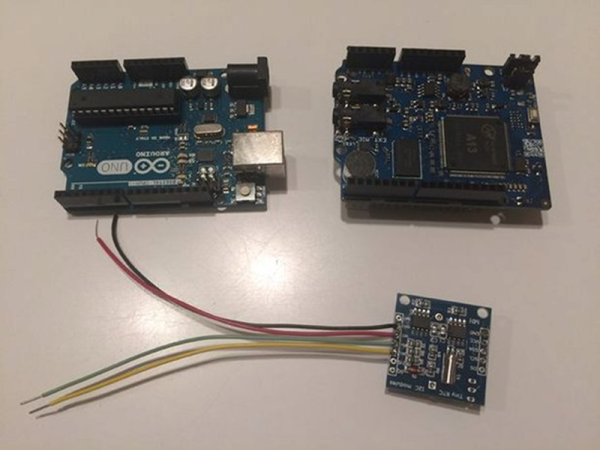
[GeraldF6] built an Arduino-based clock. That’s nothing new but thanks to a MOVI board (ok, shield), this clock has voice input and output as you can see in the video below. Unlike most modern speech-enabled devices, the MOVI board (and, thus, the clock) does not use an external server in the cloud or any remote processing at all. On the other hand, the speech quality isn’t what you might expect from any of the modern smartphone assistants that talk. We estimate it might be about 1/9 the power of the HAL 9000.

Continue reading “Arduino Clock Is HAL 1000” →

A DIY, Visual Alexa

Talking to computers is all the rage right now. We are accustomed to using voice to communicate with each other, so that makes sense. However, there’s a distinct difference between talking to a human over a phone line and conversing face-to-face. You get a lot of visual cues in person compared to talking over a phone or radio.

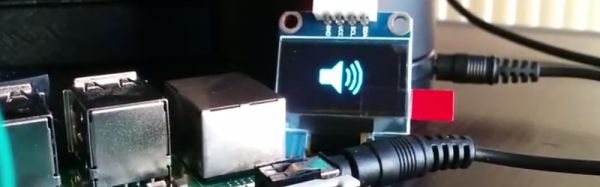
Today, most voice-enabled systems are like taking to a computer over the phone. It gets the job done, but you don’t always get the most benefit. To that end, [Youness] decided to marry an OLED display to his Alexa to give visual feedback about the current state of Alexa. It is a work in progress, but you can see two incarnations of the idea in the videos below.

A Raspberry Pi provides the horsepower and the display. A Python program connects to the Alexa Voice Service (AVS) to understand what to do. AVS provides several interfaces for building voice-enabled applications:

  • Speech Recognition/Synthesis – Understand and generate speech.
  • Alerts – Deal with events such as timers or a user utterance.
  • AudioPlayer – Manages audio playback.
  • PlaybackController – Manages playback queue.
  • Speaker – Controls volume control.
  • System – Provides client information to AVS.

We’ve seen AVS used to create an Echo clone (in a retro case, though). We also recently looked at the Google speech API on the Raspberry Pi.

Continue reading “A DIY, Visual Alexa” →

Raspberry Pi Want A Cracker?

If you watch the old original Star Trek, you’ll notice that the computers on board the Enterprise don’t look much like our computers (unless you count the little 3.5 inch floppies that looked pretty close to the real thing). Then again, the Enterprise didn’t need keyboards and screens since the computers did a pretty good job of listening and speaking to humans.

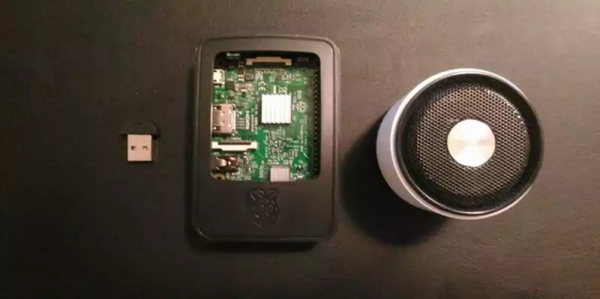
We aren’t quite to the point where you can just ask the computer some fuzzy open-ended question like Captain Kirk did, but we do have things like Echo, Siri, and Google Now that do a fair job of listening to you and replying. In fact, Google provides an API that can do speech recognition and generation. [Giulio] used some common Python libraries to add speech I/O to a Raspberry Pi.

Continue reading “Raspberry Pi Want A Cracker?” →

Talking Star Trek

Speech generation and recognition have come a long way. It wasn’t that long ago that we were in a breakfast place and endured 30 minutes of a teenaged girl screaming “CALL JUSTIN TAYLOR!” into her phone repeatedly, with no results. Now speech on phones is good enough you might never use the keyboard unless you want privacy. Every time we ask Google or Siri a question and get an answer it makes us feel like we are living in Star Trek.

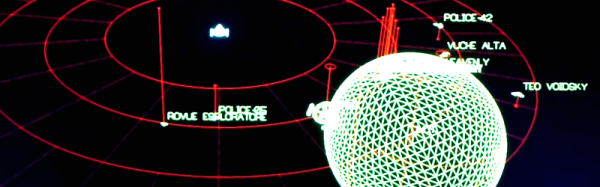
[Smcameron] probably feels the same way. He’s been working on a Star Trek-inspired bridge simulator called “Space Nerds in Space” for some time. He decided to test out the current state of Linux speech support by adding speech commands and response to it. You can see the results in the video below.

Continue reading “Talking Star Trek” →

Roll Your Own Amazon Echo On A Raspberry Pi

Speech recognition coupled with AI is the new hotness. Amazon’s Echo is a pretty compelling device, for a largish chunk of change. But if you’re interested in building something similar yourself, it’s just gotten a lot easier. Amazon has opened up a GitHub with instructions and code that will get you up and running with their Alexa Voice Service in short order.

If you read Hackaday as avidly as we do, you’ve already read that Amazon opened up their SDK (confusingly called a “Skills Kit”) and that folks have started working with it already. This newest development is Amazon’s “official” hello-world demo, for what that’s worth.

There are also open source alternatives, so if you just want to get something up and running without jumping through registration and licensing hoops, you’ve got that option as well.

Whichever way you slice it, there seems to be a real interest in having our machines listen to us. It’s probably time for an in-depth comparison of the various options. If you know of a voice recognition system that runs on something embeddable — a single-board computer or even a microcontroller — and you’d like to see us look into it, post up in the comments. We’ll see what we can do.

Thanks to [vvenesect] for the tip!