From A Ten-Line Script To A Real Utility With Codex

I’m an experienced programmer, and I’ve worked in many different languages. Sometimes being a programmer is a two-edged sword. You want to accomplish something, and you can do it easily — but it can be a lot of work to do it right. Maybe more work than you want to do.

Normally, I’ll kick out a few lines of script for something I want and be done, accepting that it isn’t production-hardened. This time, however, I decided to try an AI tool to see whether they could do the work I was too lazy to do myself. While I’ve played with chatbots, I wanted to try one of the dedicated coding agents, in this case, Codex. Outside of asking ChatGPT to write a simple function or find the cause of an error message, I haven’t done much coding with AI assistance, so I was interested to see what these agents brought to the table.

A Radio Problem

The problem was simple: I wanted an easy way to put buttons on my Linux desktop that launched Internet radio stations. Sure, I could open a player and paste in a long URL, but I’m far too lazy to remember all those URLs.

I searched for a way to make Shortwave — an Internet radio player — open a URL from the command line. Apparently, you can’t. Google Gemini suggested writing a script that launches cvlc, the command-line VLC player, with the URL as an argument.

That’s easy, so I did it. Of course, then I had to find the stream URLs for all my favorite stations. It turns out that Radio Browser maintains an extensive database of stations. I considered scraping the site or using its API, but honestly, the little script was becoming too much of a project.

Besides, I was already struggling to manage the media player’s lifetime. I didn’t want a new station playing on top of one that was already running, and I wanted a command to stop playback, so the script had already grown larger than I first imagined.

My first version used a temporary file containing the player’s process ID so a future script execution could kill the old player. That usually works, but it isn’t very robust, and I knew it. But how much work did I really want to do here? I decided I had done enough and turned the rest over to Codex, OpenAI’s coding assistant.

Continue reading “From A Ten-Line Script To A Real Utility With Codex” →
FLOSS Weekly Episode 880: The Two Wolves

This week Jonathan chats with Benjamin Samuels of Trail of Bits! The conversation focuses on Patch the Planet, a new initiative to help Open Source projects deal with the fallout from AI coding and vulnerability research. What’s the unexpected dichotomy driving the polarized response to LLMs? And what does the future look like for Open Source in the age of AI? Watch to find out!

Continue reading “FLOSS Weekly Episode 880: The Two Wolves” →

LLM Moats Quickly Evaporating

In the business world, a moat is a quality of a business that makes it difficult for competitors to take that company’s profits. With how hard it is to train models for large language models (LLMs) and generative AI, it might seem like Anthropic, Open AI, and other LLM companies would have huge moats given the amount of compute it takes to build models. But open source models are quickly draining that moat, and now the only thing standing in the way of a customer using one of these models on their own hardware instead one from the larger companies is physical computing resources. [TerminalBytes] demonstrates a few of these models on personally owned computers to show the current state of the art.

[TerminalBytes] started off running the 27B version of the Qwen3.8 on a Mac Studio with 256 GB of unified RAM, which is plenty for this task. But it’s also enough to benchmark a few different models. Qwen3.6 is compared to 3.8, and then the different quants of each model are also compared. Quants are compressed versions of models that need fewer bits to store weights, meaning that the same models can run in less memory with smaller losses in fidelity. Many of these quants run on machines with 32 GB of RAM or less, encompassing many average gaming PCs. There’s even a 1-bit quant that [TerminalBytes] tested which can easily run on a machine with 16 GB, although with mixed results.

Keep in mind that this is just the current state of affairs with open LLMs. Future versions of these models are likely to optimize the number of tokens produced per unit time, or otherwise increase quality of responses while requiring less computer resources. We don’t really think that the ease of running local models will be the sole reason that the AI bubble pops, though. The fact that not every computer user is running Linux is proof enough of that.

Same As It Ever Was

Whether you like it or not, the use of LLMs to write code is kind of a big deal at the moment. We’ve been asking ourselves what, if anything, this means for us here at Hackaday. Should we try to figure out what percentage of a project was done by an actual human and how much was done by a machine? Does it really matter? What is our AI policy anyway?

Clearly, Hackaday is pro-human. We’re in it for the hackers as much as for the hacks. Our community is, like Soylent Green, made of people. It’s your inspirations and innovations that keep us reading and writing every day. And we produce 100% of our content the old-fashioned way, with projects selected through the taste and judgement of our writers, and their own words telling the story.

What about the hacks? We’ve seen a lot of projects recently that were coded with the help of an LLM. Does that diminish the work? In the end, what rings truest to us is what has always been Hackaday’s editorial guiding star: Is there something special in the hack that makes it worth talking about? Then we write about it. Was it written using vim or emacs? Did the author consult friends or a chatbot while working on the project? That’s not really relevant.

But in the past few years, the BS-generation machines have found our hobby, and we’re finding a lot more projects that don’t have any spark to them. We’re seeing circuits that make no sense, and claims that defy physics. Of course, we always have. The LLM-nonsense project is today’s version of the perpetual motion machines of old. Just like we never trust a hardware project that is all renders, seeing only AI-generated images is a huge red flag. It’s our job to separate out the wheat from the chaff for you all, but it’s something that you must be doing everyday as well.

We’ve seen amazing hacks over Hackaday’s 22-year history. Hackaday is older than YouTube and older than Stack Overflow. We’ve seen technology come and go. We’ve seen C-beams glitter in the dark near the Tannhäuser gate. (OK, maybe not.) And in the end, our AI policy is our same-old policy: we write up hacks that inspire us in the hope that they inspire you.

So if you’re using Claude to help you with the UI bits, or if you’re hand-writing it all in assembly, or wiring up the logic in diodes, we just want to see your cool hacks. And we hope that our collective signal will be so loud that we drown out the noise, at least in our own little corner of the hacker universe.

Wear Your Way Out Of AI Surveilance

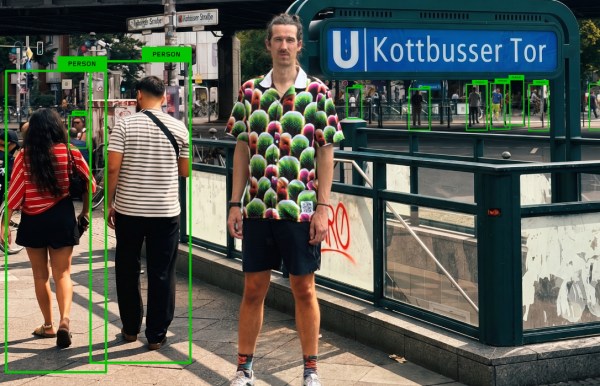
For decades now many of us have lived in surveillance societies where it’s difficult not to be within the view of a camera. When being noticed depended on the attention span of a minimum wage security guard perhaps this mattered less, but in an age of AI, the vigilance has become always-on. To address this problem the German designer [Simon Weckert] has created a fabric designed to confuse an AI scanning an image, and cause it to not recognize the wearer as a person.

The result is perhaps best described as “loud”, a pattern of saturated colors that targets the algorithms used in recognition. The tests he shows appear to work, but perhaps the most obvious thing from them is that he sticks out like the proverbial sore thumb to the eye wearing such a… vibrant garment. Also we wonder for how long it will remain effective, as algorithmic improvements seek to mitigate its attack.

This is no doubt only one salvo in what is likely to be an ongoing battle of wits. It’s certainly not the first time we’ve seen things designed to confound an AI.

Cheap AI Token Resellers: The Secret Ingredient Is Fraud

[Matt Lenhard] has an interesting writeup explaining exactly how fraudsters offer access to cutting-edge AI models at a tenth of the price. Perhaps unsurprisingly, the secret is to get tokens for free from anywhere they can and by any means necessary. Then wrap them in a pretty relay API, and sell access to it.

Relaying tokens is not by itself a shady practice. That distinction belongs to services that obtain tokens fraudulently, opening the door to selling them at rates far below market value. This practice is widespread and profitable, in part because the abuse is so hard to pin down and stop.

One source of tokens is free credits on new accounts. New accounts are spooled up as fast as possible, hammered until they’re empty, then it’s done all over again. Another method is to sign up as pay-after, possibly with a stolen card, and simply ensure the account has no valid payment method once the bill comes due. Or set up a temporary card, pay some minimum up front and consume as much as possible, then initiate a chargeback. It doesn’t matter if individually each of these doesn’t amount to much before they get flagged, because it’s being leveraged relentlessly on a massive scale by automated systems.

There are the shadier methods, too. Fraudsters don’t just target providers directly. Consumer software products with AI features get reverse-engineered, then the back ends hammered for all they are worth. Poorly-coded support chatbots can be highjacked into serving fraudsters’ traffic instead of just their own. It doesn’t actually matter where the tokens come from, after all. As long as the fraudsters are obtaining them for free (or at least below their costs) then it’s profit.

That last point is one [Matt] zeroes in on with advice on how to mitigate this abuse. He goes into detail in his writeup but what it comes down to is recognizing that it’s a numbers game. Fraudsters depend entirely on obtaining tokens for free, or nearly free. So just like using an AI to keep phone scammers tied up, anything that raises friction increases the fraudster’s costs, in turn encouraging them to find an easier target.

AI Book Scanning: Just What Is A Rare Book?

One of the stories of the last few weeks has been that AI companies have been scanning books in very large numbers in order to train their models with content guaranteed to have been written before 2002, and thus AI free. It’s caused some outrage, because of the size of the operation, and because the scanning process is destructive. In particular the phrase being bandied around is that these are rare books, and it’s this phraseology I find problematic. I think it’s time to unpack why that is the case.

It’s Not Book Burning, Folks

Before I worked for Hackaday I had a long career in and around the publishing industry, mostly on the electronic side, but from time to time crossing paths with my colleagues in the world of paper-based publishing. I understand the appeal of a good book, I’ve spend a lot of my life among bibliophiles, and let’s just say I own a few books myself. In particular I understand the symbolism of destroying books, bringing to mind as it does the actions of repressive regimes. I have stood in Bebelplatz in Berlin where the photo of Nazi student organisation members burning the library of Magnus Hirschfeld’s institute was taken in 1933, and if you know me, you’ll have an idea why that’s close to home. But for all that, what the AI companies are doing is not the same thing.

In this case they’re destroying the books for two reasons. Firstly, as I remember from a previous employer in the publishing world, it’s much easier to digitise a stack of papers than it is a bound book. Thus I’m pretty sure that’s one reason they remove the binding before digitising the pages. Then secondly, as I understand it it’s a copyright issue. If they buy a book, digitise it, and destroy the physical copy, they can legitimately claim that only one copy of it exists, and they hope, sidestep copyright claims from publishers. Continue reading “AI Book Scanning: Just What Is A Rare Book?” →