A Free Cloud AI

If you would like an AI “personal agent” but don’t want your data on some opaque cloud computer, there’s a new option that appears to be somewhat nicer: [rociiu] has talorys, an AI agent that runs in your Cloudflare account. True, it is still on a cloud computer, but it is your account on a cloud computer. It is designed so you can use it on Cloudflare’s free account with reasonable limits, and the code running is all on GitHub, so you can — if you are so inclined — look to see what it is doing. The data, too, is all in your cloud instance.

This seems like a reasonable compromise. Cloudflare provides the hosting, and the software in your virtual computer does all the work. At least, that’s how it is promoted. Honestly, we haven’t combed over the code, but the assertion is “Free-tier friendly… no telemetry.”

We are fairly sure they are using Cloudflare’s AI engines, too, so it would be interesting to see how much of your data they could, in theory, harvest in transit. Of course, your data is still in the cloud, so if you are really worried about privacy, this might not be for you. But since everything is in your account and open, you can at least have more control over what’s there. For example, you can easily download or delete your data. You can even see exactly what prompts it uses.

Continue reading “A Free Cloud AI” →

AI On Your Gaming PC

If you want to experiment with LLMs, you typically have a choice of sending your requests to someone else’s computer or fielding a very large GPU and CPU setup to run models locally. However, a recent crop of projects aims to bring bigger models to much more modest hardware.

One example is Strata, a project from [Niko1221], which lets you run a 125-billion-parameter LLM on hardware you might already have for gaming. It won’t run on your old Pentium laptop, but it doesn’t require a supercomputer-like farm of graphics cards, either.

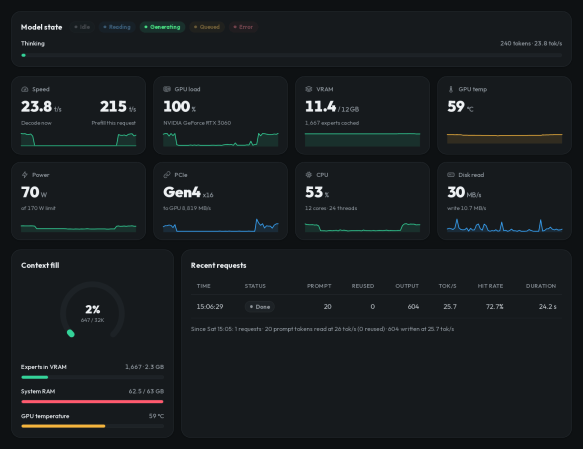
Strata can use several Qwen3.8 model variants, including different quantizations of the original model as well as coding and other specialized versions. Qwen3.8-Flash-Next is a mixture-of-experts model containing 24,576 small experts, of which only ten are needed for each token. The clever part is that Strata effectively treats VRAM as a cache for the much larger model. Frequently used experts stay on the GPU, while the complete collection normally remains in system RAM. The model also includes a roughly 29 GB lookup table that stays on the SSD and is accessed as needed.

The software also uses the model’s multi-token prediction machinery for speculative decoding, allowing several candidate tokens to be checked in a single pass. According to the project, an RTX 5070 with 12 GB of VRAM can produce roughly 50 to 90 tokens per second, depending on quantization. Tokens, of course, aren’t usually entire words, but it is still a respectable clip, once everything gets set up.

We did have some trouble setting everything up due to some incompatibility with the NVIDIA C compiler, our gcc version, and some headers, but your problems will surely be different. The setup.sh file asks you a few questions on the first run. After that, it just handles your selected startup options, which can take a few minutes while everything loads.

Once running, Strata lets you interact through a web browser. It also exposes OpenAI- and Anthropic-compatible APIs on localhost, so existing chat front ends, coding assistants, and other tools can use the local model without much special handling. Of course, you can’t expect its answers to compete with the big models out there for every task. When asking about Hackaday, for example, it got a lot of it right but also got confused about who founded the site and our authors (unless we forgot that [Tom Nardelli] once wrote some posts). Turning up the “thinking level” and turning down the temperature didn’t help much, although it did move its confusion to different facts. It did better when asked to identify some problem code or outline how to port a particular C compiler to a new target.

You’ll still want at least 32 GB of system RAM, 12 GB of VRAM, and around 80 GB of storage, so “modest” is relative. Still, it’s a neat demonstration of how mixture-of-experts models and some clever memory management can stretch ordinary PC hardware surprisingly far.

These economical LLMs can even run on older hardware, just slower.

Your AI Ham Radio Buddy

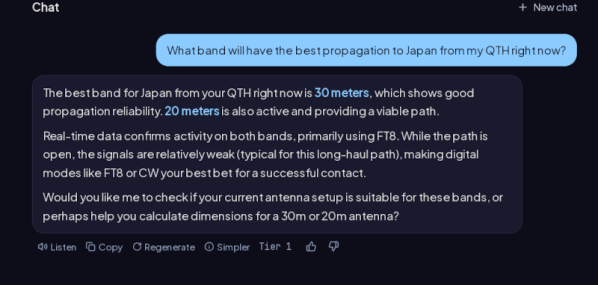
AI chatbots are everywhere these days, and they seem to “know” about everything. But while that is a strength, it can sometimes be a weakness because it isn’t laser-focused on one topic. Not so with this Ham-radio-centric chatbot called HamGPT. The service is clearly built on another GPT engine but understands how to retrieve data from common ham radio sources, such as the FCC database, propagation reports, and the like. It didn’t, however, seem to have access to ham radio-related books, magazine articles, or other “static” data that we could tell.

You do have to sign up for an account, which includes providing your callsign and location. There is a free tier that allows a limited number of queries per day, so you can try it to see if it is useful for you without subscribing.

Continue reading “Your AI Ham Radio Buddy” →

Trying Pair Programming With An LLM Chatbot

When it comes to software developers, there are a few distinct types. For example, the extroverted, chatty type, who is always going out there to share the latest and newest libraries and projects with everyone, and is very much into bouncing ideas off others, regardless of whether they know what you’re talking about. Then there is the introverted loner, who prefers to tackle programming challenges by bouncing things around inside their own minds and going on long walks to mull things over before committing to anything significant.

This leads to interesting scenarios when it comes to management-enforced ‘optimization’ strategies, like Pair Programming. This approach involves two developers sharing the same computer and keyboard, theoretically doubling the effective output by some kind of metric, but realistically often leading to at least one side feeling pretty miserable and disconnected unless you put two of the chatty types together.

As a certified introverted loner developer, the idea of using an LLM chatbot as a coding assistant naturally triggers unpleasant flashbacks to hours of forced awkward pair ‘programming’. However, maybe using an LLM chatbot could be more pleasant because you can skip the whole awkward socializing bit. In order to give it a shake, I put together a little experiment to see whether LLM-based coding assistants is something that I could come to appreciate, unlike pair programming.

Continue reading “Trying Pair Programming With An LLM Chatbot” →

Reverse-Engineering Human Cognition And Decision Making In A Modern Age

Cognitive processes are not something that we generally pay much attention to until something goes wrong, but they cover the entire scope of us ingesting sensory information, the processing and recalling thereof, as well as any resulting decisions made based on such internal deliberation.

Within that context there has also long been a struggle between those who feel that it’s fine for humans to rely on available technologies to make tasks like information recall and calculations easier, and those who insist that a human should be perfectly capable of doing such tasks without any assistance. Plato argued that reading and writing hurt our ability to memorize, and for the longest time it was deemed inappropriate for students to even consider taking one of those newfangled digital calculators into an exam, while now we have many arguing that using an ‘AI’ is the equivalent of using a calculator.

At the root of this conundrum lies the distinction between that which enhances and that which hampers human cognition. When does one merely offload tasks to a device or object, and when does one harm one’s own cognition?

Continue reading “Reverse-Engineering Human Cognition And Decision Making In A Modern Age” →

Despite Penalties, Lawyers Can’t Stop Using AI

Despite a few high-profile cases in recent years with lawyers getting caught using LLM-generated documents and facing disciplinary action due to this, it would seem that this is not deterring many other lawyers from following them off this particular cliff, per reporting from NPR.

We reported back in the innocent days of 2023 about the amusing case of Robert Mata v. Avianca, Inc. In this case, the plaintiff’s lawyer decided to have ChatGPT ‘assist’ with the legal filing, which ended up being filled with non-existent cases being cited, despite the chatbot’s assurance that these were all real cases. Now it would seem that this blind trust in cases cited by LLM chatbots is becoming the rule, rather than the exception.

Last year a record number of lawyers fell into the same trap, with many lawyers getting fined thousands of dollars for confabulated case citations. According to a researcher at the business school HEC Paris, who is keeping a worldwide tally, the count so far is 1,200, of which 800 originate from US courts.

Unsurprisingly, penalties are also increasing in severity, with monetary penalties passing the $100,000 and some courts demanding that any use of ‘AI’ be declared up-front. Whether or not the popularity of LLM chatbots among US lawyers is simply due to the massive caseload that digging through cases in Common Law legal systems entails has not yet been addressed, but that undesirable shortcuts are being taken is undeniable.

Remember that it’s easy to point and laugh, but the next case could involve the lawyer handling your delicate situation.

Living In The (LLM) Past

In the early days of AI, a common example program was the hexapawn game. This extremely simplified version of a chess program learned to play with your help. When the computer made a bad move, you’d punish it. However, people quickly realized they could punish good moves to ensure they always won against the computer. Large language models (LLMs) seem to know “everything,” but everything is whatever happens to be on the Internet, seahorse emojis and all. That got [Hayk Grigorian] thinking, so he built TimeCapsule LLM to have AI with only historical data.

Sure, you could tell a modern chatbot to pretend it was in, say, 1875 London and answer accordingly. However, you have to remember that chatbots are statistical in nature, so they could easily slip in modern knowledge. Since TimeCapsule only knows data from 1875 and earlier, it will be happy to tell you that travel to the moon is impossible, for example. If you ask a traditional LLM to roleplay, it will often hint at things you know to be true, but would not have been known by anyone of that particular time period.

Chatting with ChatGPT and telling it that it was a person living in Glasgow in 1200 limited its knowledge somewhat. Yet it was also able to hint about North America and the existence of the atom. Granted, the Norse apparently found North America around the year 1000, and Democritus wrote about indivisible matter in the fifth century. But that knowledge would not have been widespread among common people in the year 1200. Training on period texts would surely give a better representation of a historical person.

The model uses texts from 1800 to 1875 published in London. In total, there is about 90 GB of text files in the training corpus. Is this practical? There is academic interest in recreating period-accurate models to study history. Some also see it as a way to track both biases of the period and contrast them with biases found in data today. Of course, unlike the Internet, surviving documents from the 1800s are less likely to have trivialities in them, so it isn’t clear just how accurate a model like this would be for that sort of purpose.

Instead of reading the news, LLMs can write it. Just remember that the statistical nature of LLMs makes them easy to manipulate during training, too.


Featured Art: Royal Courts of Justice in London about 1870, Public Domain