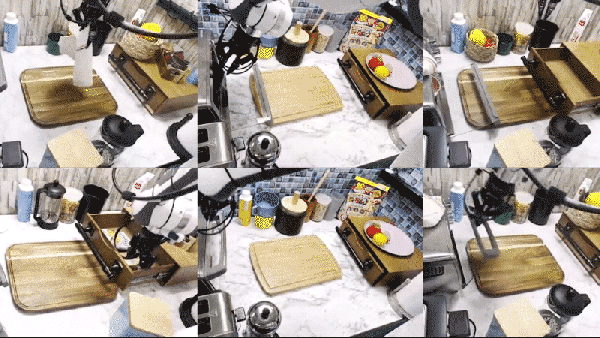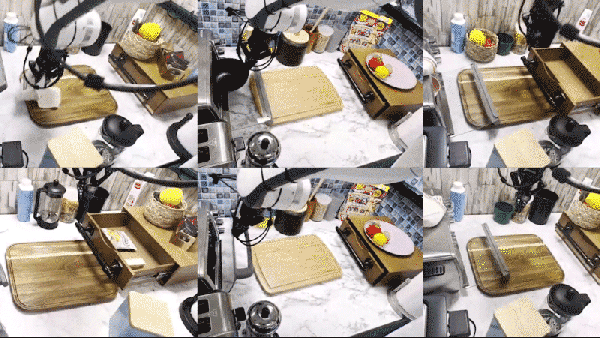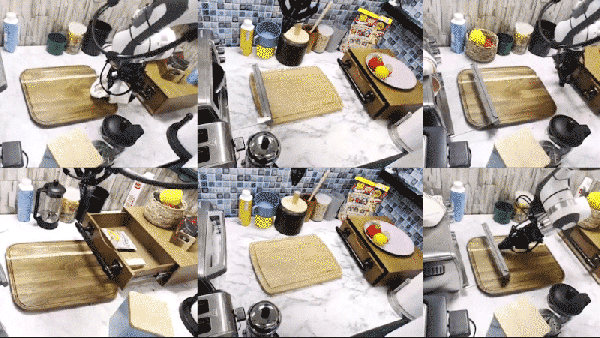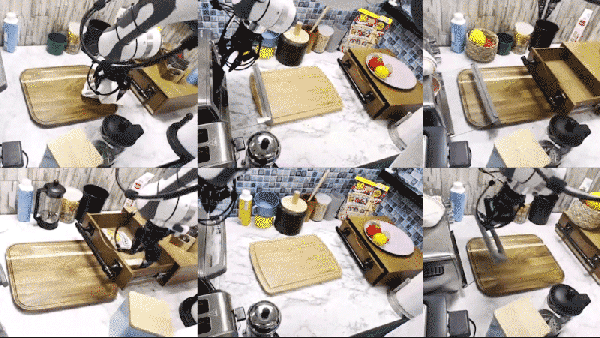
Researchers at Carnegie Mellon University have shared a pre-print paper on generalized robot training within a small “practical data budget.” The team developed a system that breaks movement tasks into 12 “skills” (e.g., pick, place, slide, wipe) that can be combined to create new and complex trajectories within at least somewhat novel scenarios, called MT-ACT: Multi-Task Action Chunking Transformer. The authors write:
Trained merely on 7500 trajectories, we are demonstrating a universal RoboAgent that can exhibit a diverse set of 12 non-trivial manipulation skills (beyond picking/pushing, including articulated object manipulation and object re-orientation) across 38 tasks and can generalize them to 100s of diverse unseen scenarios (involving unseen objects, unseen tasks, and to completely unseen kitchens). RoboAgent can also evolve its capabilities with new experiences.
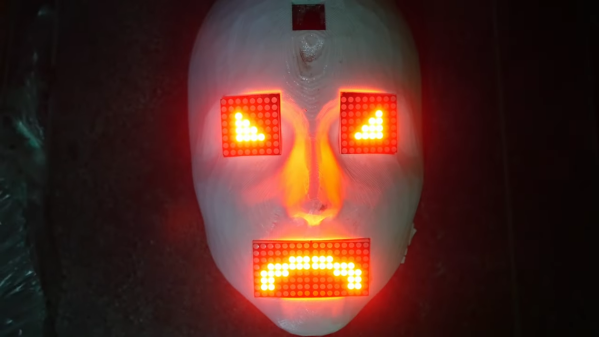
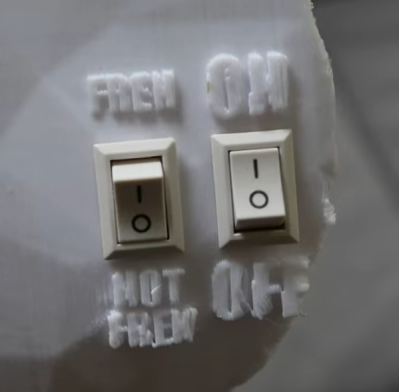 The robot face is introduced to us with a soundtrack befitting Stranger Things, or maybe Luke Million. The build was inspired by The Doorman, a creepy art piece with animatronic eyes. [Jens’] build started with a 3D model of a 3D mask, with the eyes and mouth modified to have rectangular cutouts for LED displays. The displays are run by a Raspberry Pi Pico, which generates a variety of eye and mouth animations. It uses a camera for face tracking, so the robot’s evil eyes seem to follow the viewer as they move around. In good form, the face has a simple switch—from good to evil, happy to angry. Or, as [Jens] designates the modes: “Fren” and “Not Fren.”